Agent Memory and Storage
Where an agent keeps things and how it remembers. These pages separate the layers that get conflated: the conversation context an agent carries in a session, the durable memory it reads back later, the vector index it searches, and the file storage that holds real artifacts. They cover checkpointing and resume, retrieval patterns, cost of keeping state, and the failure modes that show up when an agent is restarted. Fast.io provides the file layer, with indexing for semantic search and citation-backed chat over what it holds.
Most storage problems in agent systems turn out to be a question about which layer should hold what, so the pages settle that before recommending anything. They cover the cost and latency consequences of each choice, what survives a restart and what does not, and how to keep a store that grows every day searchable rather than merely large. Retrieval quality gets as much attention as capacity.
181 guides in this topic.
Start here
Best Knowledge Graph Tools for RAG: Enhancing Agent Memory
RAG systems often fail when they only use vector search. Adding a knowledge graph gives AI agents the context to understand how data points relate. These tools help you build that memory.
Best Cloud Storage for AI Agents: Top 7 Platforms Compared
Cloud storage for AI agents provides persistent file access, version control, and API-driven operations that let autonomous software agents store, retrieve, and share files without human intervention. This guide compares seven platforms designed for agentic workflows, from MCP-native solutions to traditional cloud providers adapting to agent needs.
Best Knowledge Base Tools for AI Chatbots in 2026
A knowledge base for AI chatbots is a structured repository of documents, FAQs, and data that an LLM-powered chatbot retrieves from to generate accurate, grounded responses. We compare 10 tools across four categories: document stores, vector databases, wiki platforms, and file management systems.
How to Perform RAG with Large Files: Strategies for Heavy Documents
Retrieval Augmented Generation (RAG) on large files requires smart chunking, indexing, and retrieval strategies to avoid context window overflows.
Best AI Agent Memory Solutions: Top 7 Tools for 2026
AI agents without persistent memory start from scratch every session, losing context and repeating much of their work. This guide compares leading memory solutions, from vector databases and agent frameworks to file-based storage, so you can pick the right architecture for context-aware agents.
8 Top AI Agent Workspace Platforms for 2026
AI agent workspace platforms provide structured environments where autonomous agents can store files, execute code, and maintain persistent context. This guide compares the top 8 solutions for developers and enterprises building agentic workflows.
All guides
10 Best Storage Solutions for RAG Pipelines in 2026
RAG pipelines need two storage layers: document stores for raw files before ingestion, and vector databases for embeddings. Most guides focus only on vector DBs while ignoring the upstream storage problem.
18 agentic workflows to run against your company brain
Your agent starts every session knowing nothing about your company. A company brain fixes that. One Fastio workspace your agents can ask, with the document behind every claim cited. This is the deep dive companion to our getting started guide. What makes the brain answer, how to keep it filled, and eighteen copy and paste agentic workflows to run against it, from launch kits and win/loss engines to renewal briefs, incident briefs, and investor updates. One for every team.
7 Best Chunking Strategies for RAG Pipelines in 2026
Chunking is the process of splitting documents into smaller segments before embedding them for retrieval. The chunk size and method directly determine whether an AI agent retrieves relevant context or noise. This guide ranks 7 chunking strategies using 2026 benchmark data and explains when each one works best.
7 Best Cloud Storage Options for Machine Learning Datasets
ML training datasets regularly exceed 1 TB, and data preparation eats up about 80% of project time according to industry surveys. Picking the right storage platform matters. This guide compares seven cloud storage options across the features ML teams actually care about: large file handling, dataset versioning, team collaboration, API access, and cost per terabyte.
7 Best Privacy-Focused Storage Solutions for AI Agents
Privacy-focused storage protects sensitive AI agent workflows. We evaluate the top 7 solutions including Fastio, Proton Drive, and self-hosted tools to help you choose the right architecture.
8 Top AI Agent Workspace Platforms for 2026
AI agent workspace platforms provide structured environments where autonomous agents can store files, execute code, and maintain persistent context. This guide compares the top 8 solutions for developers and enterprises building agentic workflows.
AI Agent Persistent Storage: How to Store Agent Data Between Sessions
AI agent persistent storage lets autonomous agents maintain state, remember context, and access files across sessions. Without it, agents start from scratch every time, losing work products and accumulated knowledge.
AI Agent Tool State Persistence: Strategies That Actually Work
AI agent tool state persistence saves intermediate tool data across sessions so agents can resume work, recover from failures, and collaborate with humans. This guide covers five persistence strategies, from in-memory buffers to workspace-native storage, with implementation examples and failure modes to avoid.
AI Automation Storage API: Persistent Storage for Autonomous Agents
An AI automation storage API provides programmatic access to persistent file storage that autonomous agents can use to read, write, and share data across sessions. Agents with persistent storage complete 3x more complex tasks compared to those relying on ephemeral memory.
Best AI Agent Memory Solutions: Top 7 Tools for 2026
AI agents without persistent memory start from scratch every session, losing context and repeating much of their work. This guide compares leading memory solutions, from vector databases and agent frameworks to file-based storage, so you can pick the right architecture for context-aware agents.
Best Cloud Storage for AI Agents: Top 7 Platforms Compared
Cloud storage for AI agents provides persistent file access, version control, and API-driven operations that let autonomous software agents store, retrieve, and share files without human intervention. This guide compares seven platforms designed for agentic workflows, from MCP-native solutions to traditional cloud providers adapting to agent needs.
Best Context Engineering Tools for AI Agents in 2026
Context engineering is the discipline of curating the right information for an AI agent's context window at the right time. This guide ranks nine tools across four categories, from retrieval frameworks and vector databases to memory layers and caching infrastructure, so you can pick what fits your agent stack.
Best Document Storage for AI Processing: Top Solutions for 2026
AI agents need somewhere to store and retrieve documents. Not every cloud storage platform is up to the task. This guide compares seven options, from raw object stores like S3 to agent-native platforms like Fastio with built-in RAG, so you can pick the right fit for your workload.
Best Embedding Models for RAG Agents in 2026
Your RAG agent is only as good as its embedding model. A weak embedding layer means missed context, irrelevant retrievals, and hallucinated answers. This guide ranks the eight best embedding models for RAG agents in 2026, with head-to-head comparisons on retrieval accuracy, latency, pricing, and context window size.
Best File Storage for Multi-Agent Systems
File storage for multi-agent systems gives AI agents a shared file layer with concurrent access controls. Agents can read, write, and coordinate on documents without conflicts or data loss. Multi-agent architectures are increasingly common in production AI systems, but file coordination bugs remain a frequent cause of pipeline failures.
Best Knowledge Base Tools for AI Chatbots in 2026
A knowledge base for AI chatbots is a structured repository of documents, FAQs, and data that an LLM-powered chatbot retrieves from to generate accurate, grounded responses. We compare 10 tools across four categories: document stores, vector databases, wiki platforms, and file management systems.
Best Knowledge Graph Databases for RAG Pipelines (2025 Guide)
Vector databases often miss the connections needed for accurate RAG. Knowledge graph databases solve this by keeping context and improving retrieval accuracy by up to multiple.4x. This guide compares the top graph databases for building reliable RAG pipelines.
Best Knowledge Graph Tools for RAG: Enhancing Agent Memory
RAG systems often fail when they only use vector search. Adding a knowledge graph gives AI agents the context to understand how data points relate. These tools help you build that memory.
Best Multimodal RAG Platforms in 2026
Standard RAG pipelines only search text, which means they miss the images, videos, and audio files that make up most enterprise data. Multimodal RAG platforms close that gap by indexing and retrieving across file types in a single pipeline. This guide ranks the best options for 2026, from dedicated multimodal engines to vector databases and intelligent workspaces with built-in indexing.
Best PDF Parsing Tools for RAG: Extract Data from Complex Documents
PDF parsing for RAG involves converting unstructured documents into structured Markdown or JSON while preserving layout, tables, and hierarchical context for optimal retrieval. This guide compares leading PDF parsers for AI agents, from Python libraries to GenAI-native services.
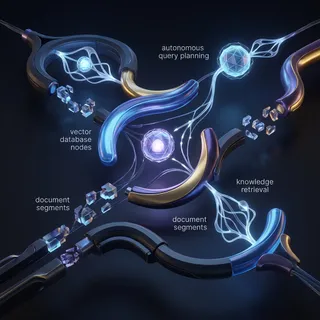
Best RAG Deployment Platforms for Production AI Agents
Best RAG deployment platforms for production AI agents pair LLMs with vector search and knowledge bases. RAG cuts down hallucinations by 40-60% for better accuracy. We picked seven leading platforms based on scaling, cost, speed, MCP support, and multi-agent features.
Best RAG Tools and Platforms for 2025
Retrieval-augmented generation tools connect large language models to external knowledge sources, letting AI generate answers grounded in your actual data rather than relying solely on training data. This guide compares 10 leading RAG platforms across frameworks, vector databases, and end-to-end solutions to help you pick the right stack.
Beyond Static Wikis: How to Choose the Best Company Wiki Software
Static wikis decay in accuracy by 30% annually due to lack of maintenance, turning valuable company knowledge into outdated friction that hinders productivity. Modern teams are moving away from passive document storage toward interactive wikis with built-in AI search, which see a 50% increase in team adoption. This guide details how to choose next-generation company wiki software, compare standard cloud drives with intelligent workspaces, and implement human-agent collaborative editing.
Building Claygent Persistent Memory: Archiving AI Research Logs
Claygent AI agents consume credits rapidly during web research tasks, making long-term audit logs of reasoning steps highly valuable. By connecting Claygent's outputs to an external, persistent workspace, growth teams can preserve and index every research step. This guide outlines how to build a queryable RAG memory layer over your historical research logs, ensuring that lead qualification reasoning remains auditable and searchable without repeated API calls.
Decentralized Storage Solutions for AI Agents Comparison
Decentralized storage spreads data across networks for AI agents. This setup offers resilience and resists censorship. Agents store simulation data, artifacts, and RAG sources persistently, and it needs to works alongside MCP tools and workflows. This guide compares IPFS, Filecoin, Arweave, and centralized options like Fastio. Decentralized storage often lacks key agent features, such as ownership transfer and built-in RAG indexing.
Deterministic Replay Storage for AI Agents
Deterministic replay storage captures every input, tool response, and file state of an agent run so the run can be reproduced exactly later. This guide covers what to capture, where to store it, and how to wire replay into eval pipelines without breaking real-time agent performance.
Dust AI Workspace: Features, Pricing, and Alternatives
Dust is an AI workspace that lets teams build custom assistants connected to company knowledge and tools. This guide breaks down what Dust actually does well, where it falls short, and how alternatives like Fastio approach the same problem differently, especially for teams running autonomous agents that need persistent file storage and MCP tooling.
Fastio API Audit Log Retrieval: A Developer's Tutorial
Audit log retrieval via the Fastio API lets developers export and monitor agent and human workspace activity for security and compliance. This tutorial covers authentication, GET /current/events/search/, and long-poll GET /current/activity/poll/{entityId} so you can automate compliance reporting.
Fastio API vs Amazon S3: Which is Better for Agent Storage?
While Amazon S3 offers raw object storage, Fastio provides an intelligent workspace with built-in MCP tools and semantic search out-of-the-box. This comprehensive comparison explores the key differences between the Fastio API and Amazon S3 for agent storage, evaluating their features, setup time, and suitability for modern AI applications. Discover which backend is right for your next agentic workflow.
Fastio API vs AWS EFS for Agent Workspaces: A Practical Guide
Your choice of storage architecture determines if your AI agents can act on their own or need human help. AWS EFS offers traditional POSIX file sharing for containers. Fastio API provides purpose-built agentic workspaces with built-in semantic search and MCP support. We compare both approaches across setup complexity, context retrieval, and moving from static files to intelligent action.
Fastio API vs Azure Blob Storage for AI Agents
Choosing the right storage API determines how quickly your AI agents can interact with files and human users. While Azure Blob Storage provides raw object storage for cloud infrastructure, the Fastio API delivers structured, intelligent workspaces optimized for AI assistants. This comparison evaluates both platforms based on developer velocity, native intelligence, and Model Context Protocol integration.
Fastio API vs Google Cloud Storage for AI Agents: 2026 Comparison
When building persistent memory for AI agents, developers often start with a raw object store. While Google Cloud Storage gives you raw buckets, the Fastio API provides a workspace designed specifically for AI agents with built-in MCP support. This comparison looks at the architectural differences, developer overhead, and operational reality of these two approaches.
Fastio API vs Supabase Storage for Agent Workspaces
Guide to fast api supabase storage agent workspaces: Picking the right backend for your AI application shapes your engineering roadmap. Developers often treat all cloud storage as interchangeable, but agentic systems have different requirements than standard web apps. This comparison looks at the differences between standard object storage and specialized agent workspaces. We explain why native tool calling, built-in semantic search, and structured human handoff save time over building custom mi
Fastio API vs Vercel Blob Storage for AI Apps
While Vercel Blob provides basic cloud storage for frontend frameworks, the Fastio API offers an intelligent workspace built for AI agents, multi-modal context, and MCP integration. When building AI applications, developers face a major architectural choice between standard object storage and specialized agent environments. This guide compares Fastio and Vercel Blob, detailing their capabilities in AI integration, file limitations, and built-in search intelligence.
Fastio vs Amazon S3: Best Storage for AI Agent Workspaces
Amazon S3 provides raw object storage, while Fastio gives AI agents an MCP-ready workspace. S3 requires developers to build custom indexing, vector databases, and permission layers from scratch. Fastio includes semantic search, multiple Model Context Protocol tools, and built-in RAG capabilities out of the box. We compare both options and show how an agent-native workspace saves developers an average of 40 hours versus building custom pipelines on top of S3.
Google Drive File Size Limits: Workarounds for AI Agent Workspaces
Google Drive limits individual file uploads to 5TB and daily uploads to 750GB, which can easily freeze multi-agent workspaces. This guide explains how to implement exponential backoff workarounds in your API pipelines and how to structure collaborative agent rooms.
How to Add Cloud File Storage to AI Slack Bots
Slack bots are great until they need to handle files. Workspace storage limits and ephemeral chat history make it hard for agents to store reports or process large documents. This guide shows you how to give your Slack bot persistent cloud storage using Fastio, so it can save and share files reliably.
How to Add File Storage to Flowise Chatflows
Flowise makes it easy to build AI agents, but managing the files they create or use can be tricky. Most default setups store files on the local disk or inside ephemeral containers, meaning you lose everything if the system restarts. This guide shows you how to connect external storage so your agent documents and outputs stay safe and accessible.
How to Add File Storage to OpenAI Agents SDK Projects
The OpenAI Agents SDK gives you tools, handoffs, and guardrails for building multi-agent systems, but it has no built-in file persistence. This guide walks through adding persistent file storage to your agents using custom function tools, so your agents can save, retrieve, and share files across sessions without losing work.
How to Add File Storage to Smolagents
Smolagents is a fast way to build AI agents, but it lacks persistent storage by default. This guide shows you how to add a cloud layer so your agents can save artifacts, handle large documents, and share results with your team.
How to Add File Storage to Vercel AI SDK Applications
The Vercel AI SDK gives you React hooks and server utilities for building AI-powered applications, but file storage for agent outputs, uploads, and artifacts requires an external solution. This guide walks through practical patterns for adding persistent file storage to your AI SDK projects, from defining storage tools to connecting cloud backends for Next.js AI apps.
How to Add Persistent Cloud Storage to SuperAGI Agents
SuperAGI agents often run in temporary environments where files are lost after the job finishes. By using Fastio as a storage tool, you can give your agents persistent cloud memory. This guide shows you how to build a SuperAGI tool to upload, retrieve, and share files programmatically.
How to Add Persistent File Storage to Dify AI Agents
Dify AI file storage connects the Dify open-source LLM platform to persistent cloud storage. This lets agents read, write, and manage files across sessions. Dify offers basic temporary uploads, but complex agents need long-term memory for documents, datasets, and media. This guide explains how to connect Dify to Fastio storage using the Model Context Protocol (MCP).
How to Add Persistent File Storage to Discord AI Bots
Discord bots are growing into capable AI agents that generate images, write code, and process documents. But they often hit a wall with Discord's 25MB file limit and temporary attachment links. This guide shows how to give your Discord bot persistent cloud storage to manage files, host generated assets, and work with users effectively.
How to Add Persistent File Storage to OpenAI Swarm
OpenAI Swarm runs multi-agent workflows that share files between handoffs. Without persistent storage, those files disappear. Fastio workspaces keep files accessible across agents. Agents upload, list, and query them in shared project spaces. This guide walks through setup with code examples.
How to Add Persistent File Storage to Relevance AI Agents
Relevance AI is a great no-code platform for building agent workflows. But its built-in storage has limits. You get a 100MB cap per file, and free plans only allow 10MB of total storage. If your agents process video, large datasets, or need long-term memory, you need external storage. This guide shows you how to add Fastio to your setup. You'll get generous, persistent cloud storage so your workflows don't hit capacity walls. This guide covers relevance ai file storage with practical exa...
How to Add Persistent Storage for LLM Tool Calling
Persistent storage for LLM tool calling keeps agent state, files, and outputs indefinitely. LLMs forget context without long-term memory. MCP workspaces let agents save data to cloud storage and resume without token limits. This guide shows how to build agent memory systems.
How to Add Persistent Storage to Flowise AI Agents
Flowise AI agents often lose files, especially in containerized deployments where local storage is temporary. This guide explains how to add cloud storage to your Flowise workflows, so agents can save, retrieve, and share files permanently without managing S3 buckets.
How to Architect Invoice Processing Agent Storage for AP Automation
Learn how to build a scalable storage architecture for AI agents that extract and validate invoice data before routing it to the right systems. According to market research, AP automation is expected to reach $3.1B by 2025. AI invoice processing reduces manual work. However, these gains only happen when agents have a central, programmatic way to access and organize documents.
How to Architect Medical Imaging AI Storage for Research
Medical imaging AI storage provides scalable, performant infrastructure for storing DICOM files, annotations, and model outputs for radiology and pathology AI applications. This guide explores architecture patterns for research and development workflows using AI agents.
How to Architect Storage for AI Agent Data Pipelines
Multi-step AI agent workflows produce 10-100x more data than their final outputs. This guide explains how to architect storage for agent pipelines to handle intermediate artifacts, enable debugging, and help with human-in-the-loop review.
How to Automate Fastio Workspace Provisioning with GitLab CI
Automating Fastio workspace provisioning with GitLab CI ensures that every deployment environment has an isolated, securely configured file storage space. By combining GitLab's CI/CD pipeline capabilities with Fastio's APIs, development teams can eliminate manual setup overhead. This guide explains how to integrate workspace creation directly into your deployment workflows, enabling ephemeral staging environments and secure coordination layers for AI agents.
How to Automate Fastio Workspaces with GitHub Actions
Guide to automating fast workspace provisioning with github actions: Setting up test environments manually slows down your deployment cycle. By using GitHub Actions to provision Fastio workspaces, you give every pull request a clean, isolated space for testing agent file interactions. This guide covers how to add Fastio workspace creation to your CI/CD pipeline, handle access credentials securely, and automatically remove temporary environments when tests finish. Automating this setup saves QA
How to Automate Fastio Workspaces with Pulumi
Automating Fastio workspaces with Pulumi lets you provision agentic storage using familiar programming languages. This infrastructure-as-code approach skips manual setup and gives AI agents reliable access to their required tools. By writing infrastructure as code, engineering teams can scale deployments consistently and prevent environment drift as projects evolve.
How to Automate Fastio Workspaces with Terraform
Terraform can provision Fastio workspaces, permissions, and folder structures through the platform's REST API, bringing infrastructure-as-code discipline to your agent environments. This guide walks through provider setup, workspace resources, permission management, and CI/CD integration for teams running multi-agent systems at scale.
How to Benchmark AI Agent Storage Performance
AI agent storage benchmarking measures performance for concurrent agent access and persistence. Unlike standard file storage tests, agent-specific benchmarks must account for multi-writer conflicts, high-frequency small-file operations, and sub-100ms latency requirements. This guide covers how to benchmark storage for autonomous agents, what metrics matter most, and how Fastio delivers performance that meets agent workload demands.
How to Build a ChatGPT Knowledge Base
A ChatGPT knowledge base uses RAG to connect your documents to ChatGPT, providing answers grounded in your files rather than generic training data. Fastio workspaces enable this with automatic indexing via Intelligence Mode, semantic search, built-in AI chat, and shareable context links. Start a 14-day Business Trial with included credits.
How to Build a Collaborative AI Knowledge Base for Teams
An AI knowledge base is an intelligent workspace where humans and AI agents collaborate on organizational knowledge. While over 70% of teams will deploy autonomous AI agents by 2026, search processes still waste time, but AI-driven knowledge access can reduce information search time by up to 35%. This guide explains how to build a collaborative AI knowledge base using auto-indexing, hybrid search, real-time cursors, and Model Context Protocol access.
How to Build a Company Brain for Human-Agent Collaboration
Building a centralized company brain is essential for organizations deploying AI agents. As teams adopt autonomous workflows, storing files in isolated, static wikis prevents agents from retrieving critical information or posting updates. This guide outlines how to establish an intelligent, live repository on Fast.io that integrates human documentation and agent outputs into a single, queryable source of truth.
How to Build a Custom RAG Application with Fastio API
Building a custom RAG (Retrieval-Augmented Generation) application traditionally requires complex orchestration between document parsers, vector databases, and cloud storage systems. By using the Fastio API, developers can bypass this fragmented architecture entirely. Using Fastio for RAG simplifies architecture by unifying document storage, automatic parsing, and vector search in a single API.
How to Build a Multi-Agent RAG System with Shared Workspace Storage
Multi-agent architectures address the limitations of single-agent RAG systems by distributing tasks among specialized nodes. By separating document search from context synthesis, these systems achieve higher retrieval accuracy and reduce hallucinations. This guide explains how to construct a collaborative RAG pipeline using a shared workspace substrate for persistent document storage and sync.
How to Build a RAG Pipeline with Fastio API
Building a reliable Retrieval-Augmented Generation pipeline often involves managing complex infrastructure. A RAG pipeline with Fastio allows developers to ingest, embed, and retrieve document data directly from workspaces. This guide explains how to implement native document intelligence without relying on a separate vector database.
How to Build an Agentic Workspace with the Fastio API
An agentic workspace built with the Fastio API provides persistent memory, file sharing, and tools for autonomous systems. By offloading file management to Fastio, you reduce context window overload and enable true multi-agent collaboration. This guide explains how to connect your LLM to the Model Context Protocol (MCP) server, set up persistent workspaces, and coordinate agent workflows via realtime events.
How to Build an AI Agent IoT Workspace
AI agent IoT workspaces provide persistent storage for device fleets and simulations. Agents manage sensor data, logs, and configurations in shared spaces with humans. Forecasts predict 75 billion IoT devices worldwide by 2025, so solid workspaces handle the data growth. This guide covers setup, tools, and Fastio features like MCP tools and built-in RAG.
How to Build Audio Transcription Agent Workflow Storage
Audio transcription agent workflow storage manages the full data pipeline from audio file ingestion through speech-to-text processing to structured transcript delivery. This guide covers storage architecture, file format handling, and output management for transcription agents.
How to Build CI/CD Pipelines for AI Agents with Storage
CI/CD for AI agents needs more than just code deployment. It requires managing prompts, models, and RAG datasets carefully. You need to automate agent testing, version control your artifacts, and build reliable pipelines that handle the unique storage needs of autonomous systems. By integrating specialized storage, you can make sure your agents are reliable, testable, and ready to scale.
How to Build Fastio API Caching Strategies with Redis
Caching Fastio API responses in Redis cuts down latency and prevents rate limit errors by serving file metadata from memory. This guide covers practical API caching strategies for developers, moving from basic cache-aside setups to event-driven invalidation using the WebSocket events feed. We will show you how to improve read-heavy workflows for maximum throughput so your AI agents and applications can scale without slowdowns.
How to Build Federated Workspaces for AI Agents
Federated AI agent workspaces enable distributed agents to collaborate without centralizing all data. Learn the architecture, key benefits like edge data processing, and how to implement secure handoffs in a unified environment.
How to Build GraphRAG for AI Agent Memory
GraphRAG changes how AI agents store and recall information by using knowledge graphs instead of just vector embeddings. This allows agents to understand relationships between different facts and connect dots that standard RAG often misses. By building a graph-based memory, developers can cut token usage by up to 43 times for big summarization tasks while getting much more accurate answers to complex questions.
How to Build Persistent Memory for Semantic Kernel Agents
Semantic Kernel memory lets AI agents store and retrieve information using vector embeddings. This guide covers setting up memory stores in C# and Python, moving past the built-in VolatileMemoryStore to production-ready persistence, and connecting a remote file system for large asset retrieval in RAG pipelines.
How to Build Persistent Memory in CrewAI Agents
CrewAI memory is a framework-level feature that allows agents to store and retrieve past experiences, improving collaboration and task execution over time. While default memory handles context and vectors, building persistent multi-agent systems requires managing both cognitive memory and artifact storage effectively.
How to Build Persistent Storage for Agentic Workflows
Agentic workflow storage lets autonomous agents maintain state, share files, and persist progress across long-running tasks. Without it, agents reset every session, losing context. This guide covers the difference between agent memory and storage, coordination patterns for multi-agent systems, and how to implement durable workflows that survive crashes and multi-day processes.
How to Build RAG Pipelines for Marketing Attribution
Marketing attribution suffers from fragmented data spread across dozens of platforms. A RAG pipeline connects your campaign files, reports, and analytics exports to a large language model so you can ask plain-language questions about what drove conversions. This guide walks through each stage of building one, from data ingestion to query interface.
How to Build Tool Calling Persistent Memory for AI Agents
Tool calling persistent memory stores function states between invocations. This approach allows AI agents to maintain context across complex, multi-step workflows. Without persistent state, agents forget previous tool outcomes and struggle with interdependent tasks. This guide explains how to implement persistent tool memory to improve agent reliability and accuracy.
How to Checkpoint and Resume AI Agent Execution
AI agent checkpointing saves execution state to allow recovery from failures. Learn patterns for implementing reliable resume logic using persistent storage to prevent data loss and reduce API costs.
How to Choose AI Storage: Fastio API vs Supabase Storage
Your storage backend dictates what your AI agents can actually do. Supabase Storage works great for standard web apps, but Fastio API gives agents native MCP support and advisory file locks. Here is how they compare for agent workloads.
How to Choose Between Fastio API vs Box API for Agent Workspaces
Box API handles traditional enterprise document management, while Fastio API provides native vector search and intelligence features built for AI agent workspaces. This comparison examines how both platforms handle API access, file uploads, built-in RAG capabilities, and Agent-to-Human handoffs. Developers evaluating storage for their language models need to understand why autonomous systems rely on native tooling protocols instead of standard synchronization frameworks.
How to Choose the Best Vector Database for AI Agents (2026)
Vector databases serve as the long-term semantic memory for AI agents, allowing them to recall context across sessions and vast datasets. With the vector database market projected to reach $5 billion by 2028, choosing the right backend for your agent matters. This guide compares the top solutions in 2026, from specialized databases like Pinecone and Weaviate to integrated storage solutions like Fastio.
How to Choose: Fastio API vs Dropbox API for Agent Storage
When evaluating the Fastio API vs Dropbox API for agent storage, developers face a distinct choice between an agent-native architecture and legacy file syncing. While the Dropbox API is designed for human file syncing, the Fastio API is purpose-built for AI agents, offering native MCP integration and semantic search. This comparison explores the technical differences, integration overhead, and pricing models to help you select the best storage backend for your autonomous workflows.
How to Configure Claygent RAG Document Storage for GTM Research
Sales intelligence teams struggle to scale automated B2B research because of LLM hallucination rates in agentic workflows. Implementing a dedicated Claygent RAG document storage architecture helps ground prompts in verified company documentation. This guide details how to configure a Fastio workspace as an external retrieval database to build reliable go-to-market data pipelines.
How to Configure Claygent Workspace Tools and Custom Context in Clay
Sales teams employing autonomous AI agents report an average 34% reduction in prospect research time. However, standard setups lack deep company context. Configuring Claygent workspace tools with custom context files and tailored builder settings ensures highly accurate results. This guide walks through configuring Claygent, optimizing AI model settings in Clay, and managing research assets using a persistent external storage layer.
How to Configure txtai Storage Solutions for Embeddings Databases
txtai storage solutions save vector embeddings and source documents for semantic search and RAG apps. txtai defaults to local files, but production workflows need scalable backends like PostgreSQL or cloud object storage. This guide covers the best storage architectures for your embeddings database.
How to Connect a Linux File Server to Intelligent Agent Workspaces
Connecting a traditional Linux file server to autonomous agents requires a bridge that translates raw directory hierarchies into queryable context. By wrapping standard network shares in a Model Context Protocol endpoint, developer teams can establish shared, collaborative rooms for multi-agent workflows. This guide covers NFS and Samba setups, custom bash directory indexing, and remote cloud workspace mappings.
How to Create Fastio Workspaces Programmatically via API
Programmatic workspace creation allows developers to dynamically spin up isolated, intelligence-ready Fastio environments via API. Instead of manually clicking through a dashboard to set up each workspace, you can automate the entire process with a single POST request. This approach reduces client onboarding time from hours to seconds and enables automated provisioning for multi-agent systems.
How to Design and Build Scalable AI Workflows
AI agents perform up to 4x better when equipped with persistent memory interfaces. This guide explains how to design and build scalable AI workflows around a centralized company brain, using structured schemas and human-in-the-loop review gates.
How to Design Multi Agent Workflows in Shared Workspaces
Orchestrating multi agent workflows requires a reliable state layer. Learn how to configure a shared directory as the single source of truth for agent transitions, coordinate pipelines, and manage human handoffs.
How to Design Repeatable Workflows in a Company Brain
A repeatable company brain workflow is a sequence of document events, metadata checks, and human handoffs that runs directly on shared storage, without anyone manually checking folders for new files. This guide covers designing these systems with a WebSocket events feed, a live activity feed, and Metadata Views, then routing human review through version history and ownership transfer.
How to Diff AI Agent File Checkpoints Without Chasing False Positives
Checkpoint diffing compares the files an agent produced across two runs to detect regressions, drift, or unintended changes. Byte diffs light up on every whitespace shuffle, so most teams need structural and semantic comparisons layered on top. This guide walks through the three strategies, when each one fits, and how to wire them into an agent workspace without drowning in noise.
How to Enforce AI Agent Quotas per Workspace
Per-workspace quota enforcement applies storage, request, and token limits to each agent workspace independently so one workspace cannot exhaust another's budget. This guide covers the five quota dimensions that matter, how to structure nested limits for multi-tenant agent platforms, and how to detect and stop runaway agents before they burn through a month of spend in an afternoon.
How to Extract Metadata from Google Workspace Files via API
Google Workspace files live entirely in the cloud, so there is no local file to parse with traditional metadata tools. This guide shows you how to use Google's Drive, Docs, Sheets, and Slides APIs to retrieve file properties, revision history, permissions, custom metadata, and document-specific structures programmatically.
How to Extract Metadata from SVG Vector Files
SVG files store metadata as XML elements and attributes, including title, desc, Dublin Core RDF blocks, viewBox dimensions, and editor-specific namespaces from tools like Inkscape and Adobe Illustrator. This guide covers where that metadata lives, how to extract it with command-line tools, Python, and JavaScript, and how to manage SVG metadata across large asset libraries.
How to Fix 'File Too Large for Destination File System' in Agentic Workspaces
The file too large for destination file system error interrupts AI agents working in containerized environments. This guide explains why the FAT32 4 GB limit occurs and provides a 3-step troubleshooting guide to resolve file limits in local, container, and cloud workspaces.
How to Give AI Agents Secure Cloud File Storage
Autonomous agents need more than vector memory. They need actual file storage to read documents, generate reports, and process media. Here's how to give your AI agents persistent, secure cloud storage that works with any LLM.
How to Handle File Storage in n8n AI Agent Workflows
n8n AI agents need persistent storage to save files between workflow runs.
How to Implement Agentic RAG: A Complete Technical Guide
Agentic RAG is a retrieval-augmented generation pattern where autonomous agents dynamically decide what to retrieve, when to retrieve it, and how to use retrieved information. Unlike basic RAG that retrieves once then generates, agentic RAG enables multi-step reasoning with iterative retrieval cycles. This guide covers the complete implementation including architecture design, storage patterns, query planning, and production deployment.
How to Implement AI Agent Caching Strategies
Effective AI agent caching strategies store frequently used prompts, tool results, and embeddings so your agent can skip redundant LLM calls. By implementing a multi-layer caching approach, developers can cut API costs by over 50% and reduce response times from seconds to milliseconds.
How to Implement AI Agent Episodic Memory
Episodic memory enables AI agents to recall specific past experiences, learn from mistakes, and improve performance on repeated tasks. This guide covers the architecture, data schemas, and implementation strategies for building strong event-based memory systems that scale to production workloads.
How to Implement AI Agent Long-Term Memory Solutions
Long-term memory enables AI agents to retain context, user preferences, and learned behaviors across sessions. This guide explores the three types of agent memory (episodic, semantic, and procedural) and compares storage solutions from vector databases to file-based systems for persistent state management.
How to Implement AI Agent Memory Persistence
Memory persistence keeps agent knowledge across sessions. Without persistent storage, AI models suffer from amnesia and restart their reasoning from scratch on every run. This guide explains how to implement working buffers, vector databases, and workspace-integrated memory to build persistent agents that continuously learn and adapt over time.
How to Implement AI Agent State Checkpointing
AI agent state checkpointing saves an agent's context and progress to keep it running reliably. With long-running tasks failing up to 30% of the time, proper checkpointing can save over 60% of wasted processing. This guide shows you how to use file-based storage to make your agents persistent.
How to Implement AI Agent Storage Encryption
As autonomous systems take on more responsibility, securing their persistent data has become a critical challenge. AI agent storage encryption protects persistent memory and tools from unauthorized access, ensuring that sensitive context remains private. This guide covers the essential strategies for encrypting agent data, from at-rest protection to securing MCP-integrated multi-agent workflows.
How to Implement AI Agent Storage Replication
AI agent storage replication is the process of synchronizing agent state, memory, and artifacts across multiple physical locations to ensure high availability. In distributed systems, a single server failure can wipe out hours of agent processing time. Without replication, distributed agents lose significant portions of their state during outages, leading to expensive restarts and errors.
How to Implement AI Agent Workflow State Persistence
Workflow state persistence lets AI agents keep context, progress, and results across multiple cycles. Without it, long-running automations break easily.
How to Implement Cross-Workspace Search with Fastio API
Cross-workspace search with the Fastio API allows centralized systems to securely query data across multiple isolated agent environments using federated search techniques. This comprehensive guide covers how to retrieve workspace lists, iterate queries efficiently, handle rate limits, and aggregate multi-tenant data for seamless AI agent workflows.
How to Implement Decentralized Storage for AI Agents
Decentralized AI agent storage distributes agent state across multiple nodes for resilience and scalability. Unlike centralized systems, it uses peer-to-peer networks to store agent memory, artifacts, and shared data, reducing risks of single-point failures, censorship, or vendor lock-in. AI agents generate diverse data: conversation histories, tool call outputs, generated images, reports, and coordination state for multi-agent systems.
How to Implement File Persistence for Tool Calling Agents
File persistence ensures tool outputs survive agent restarts, creating reliable state across multi-tool chains. When an AI agent generates a report, writes code, or analyzes data, that output must persist beyond a single execution session. This guide explores how to implement persistent file storage for tool-calling LLMs, including multi-tool chain examples that most solutions miss.
How to Implement LangGraph Persistence for Long-Term Memory
LangGraph persistence allows AI agents to maintain state and memory across multiple sessions by saving graph checkpoints to a database. This guide covers how to set up Postgres checkpointers, manage long-term agent memory, and handle human-in-the-loop workflows without losing context.
How to Implement Local-First Storage for AI Agents
Local-first storage for AI agents is an architecture pattern where agents read and write data locally first, then sync changes to cloud storage. This approach eliminates network latency for key operations, enables full offline capability, and reduces API costs. By prioritizing local state, developers can build faster, more resilient agents that aren't dependent on constant internet connectivity.
How to Implement Memory Compaction for Long-Running AI Agents
Long-running AI agents lose track of earlier reasoning as conversations grow beyond context window limits. Memory compaction solves this by summarizing, pruning, and compressing conversation history while preserving the facts and decisions that matter. This guide walks through five production-tested compaction strategies, from anchored summarization to hybrid graph-vector retrieval, with concrete implementation patterns for each.
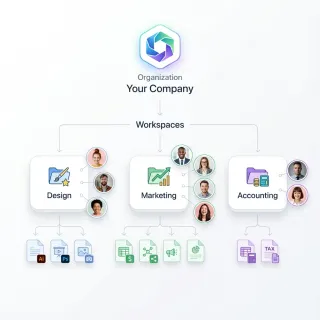
How to Implement Multi-Tenant Workspaces with Fastio API
Implementing multi-tenant workspaces with the Fastio API allows B2B AI applications to guarantee strict data isolation between different customer organizations. Each tenant receives a dedicated organization containing isolated workspaces, with granular permissions and scoped AI features like RAG. This approach simplifies compliance by limiting agent data context to specific tenants and supports scaling through programmatic API calls.
How to Implement Persistent Storage for AutoGen using Fastio API
Adding persistent storage to AutoGen via Fastio API allows multi-agent conversations to share and modify files reliably across sessions. While most AutoGen tutorials rely on local file systems, those approaches break down in serverless or distributed production environments. This guide explains how to replace default local I/O with cloud-native workspaces designed for agentic workflows, enabling reliable and scalable multi-agent systems.
How to Implement Tool Calling with Persistent File State for AI Agents
AI agents that call tools across multiple LLM invocations need durable file state to avoid losing context, repeating work, or corrupting outputs. This guide covers the architecture patterns, storage options, and practical implementation steps for building agents with persistent file state, including workspace-based approaches that give both agents and humans access to the same files.
How to Integrate Dify AI with External File Storage
Dify is an open-source platform for building AI applications with visual workflows. Its built-in file handling works for simple uploads, but agents that generate reports, archive data, or share documents need persistent external storage. This guide shows you how to connect Dify to Fastio using Custom Tools and OpenAPI so your agents can upload, retrieve, and share files across sessions.
How to Integrate Dify File Storage for Agents
Dify defaults to local file storage, which limits scalability and agent capabilities.
How to Integrate Fastio API with AutoGPT Workspaces
AutoGPT agents run autonomously but struggle with ephemeral local storage, making outputs hard to share or persist across sessions. Integrating Fastio API gives them reliable cloud workspaces for files, with built-in AI search, sharing, and human handoff. This guide walks through setup, from agent accounts to custom tools calling Fastio endpoints. Agents can upload artifacts, query documents via RAG, create branded shares, and transfer ownership to teams.
How to Integrate Langflow File Storage
Langflow agents delete files when sessions end. This guide shows three ways to add permanent storage: native local volumes, complex S3 custom components, and the modern Model Context Protocol (MCP) approach. We'll show you how to build agents that can read, write, and search files across sessions without managing infrastructure.
How to Manage AI Research Agent Storage
Research agents create huge amounts of data. This guide shows how to structure, store, and retrieve findings effectively using storage solutions made for autonomous workflows.
How to Manage Amazon Bedrock Agent File Storage
Amazon Bedrock agent file storage determines how AI agents interact with your documents and where they save their work. By connecting AWS S3 with Bedrock Knowledge Bases and action groups, you can build agents that handle private data and create persistent files. This guide walks through the setup for managing files in Bedrock, from indexing documents to sending finished reports to users. Understanding these storage patterns helps move agents from simple chat bots to useful production tools.
How to Manage an AI Agent Knowledge Base That Stays Accurate
AI agent knowledge base management is the practice of maintaining, updating, and monitoring the document collections that agents use for retrieval-augmented generation. This guide covers everything after the initial setup: versioning strategies, staleness detection, access control, and a weekly maintenance checklist you can start using today. If your agents are returning outdated answers, the problem is almost always the knowledge base, not the model.
How to Manage Fastio Workspace Permissions API
The Fastio workspace permission management API lets developers set granular role-based access control (RBAC) for AI agents and teams. Use it to restrict access at organization, workspace, folder, and file levels with roles like viewer, editor, agent, and owner. This ensures agents only access authorized files, filling the gap in competitor docs on scoping permissions for autonomous agents.
How to Manage Financial AI Agent Document Storage
Financial AI agent document storage is the secure management of financial documents, such as statements, contracts, reports, and compliance records, that autonomous agents process, analyze, and deliver within financial services workflows. This guide covers the essential requirements for building agentic financial systems.
How to Manage LlamaIndex Storage for Production RAG Applications
LlamaIndex storage handles the persistence of document embeddings, index metadata, and raw document nodes required for RAG applications. By default, everything lives in memory and disappears when your script exits. This guide walks through StorageContext configuration, the differences between vector stores and document stores, and how to manage the source files your pipeline depends on.
How to Manage LLM Context Windows Effectively
LLM context management is the practice of efficiently handling the limited context window of large language models by selectively loading, summarizing, and storing information. With context windows ranging from 8K to 200K tokens and poor management wasting up to 40% of API costs, mastering these strategies is essential for building production AI agents.
How to Manage Mistral AI Agent Storage
Mistral AI agent storage handles files, tool results, and state for reliable agent workflows. Mistral's Agents API maintains conversation state across sessions. Production setups still need external storage for files and artifacts. This guide shares best practices, compares options, and shows Fastio setup steps.
How to Manage Persistent State for LLM Tool Calls
Persistent state for LLM tool calls keeps context across sessions and interruptions. Without it, agents lose progress on complex tasks like multi-step workflows or long-running processes. This guide covers options from simple caches to durable workspaces. Fastio workspaces provide persistent storage through MCP tools and shared files.
How to Manage Retail Inventory Storage for AI Agents
AI agent retail inventory storage enables real-time stock tracking and SKU file management in shared workspaces. Retail teams use agents to update inventory files, query stock levels via semantic search, and hand off reports to humans. Fastio workspaces give agents persistent storage with built-in RAG for querying inventory data. Agents manage CSV, JSON, or spreadsheet files containing SKUs, quantities, and supplier info. With a consolidated MCP toolset and Ripley, the built-in RAG agent, setup takes minutes.
How to Manage Storage for Unity AI Agents
Unity AI agents need storage to save models, training data, and assets across game sessions. Production teams handle large volumes of dynamically generated files. This guide compares storage options and shows how to implement with Fastio workspaces.
How to Master Context Engineering for AI Agents
Context engineering is about how you structure the data, tools, and instructions an AI agent sees. While prompt engineering is about how you talk to a model, context engineering is about what that model actually knows. This is a big deal for developers building agents that handle long-term memory, files, and complex tools. Research shows that agents with a structured context pipeline finish tasks 60% more reliably than those just using raw prompts.
How to Master Edge Computing Storage for AI Agents
Edge storage for AI agents handles data at the source for real-time processing, overcoming the latency and bandwidth limits of cloud-only systems. As autonomous agents move from data centers to devices, mastering local persistence and synchronization is critical for performance. This guide explores the best databases, architecture patterns, and hybrid strategies for deploying strong edge AI agents.
How to Master Haystack AI File Storage for RAG Pipelines
Haystack AI file storage uses two systems: one for raw source files and another for processed vector data. While Haystack works well with vector stores like Weaviate and Elasticsearch, managing the original PDF, TXT, and media files is often a problem for production AI agents.
How to Migrate Agent Storage to Fastio API
Migrating agent storage to Fastio involves mapping flat bucket structures into semantic workspaces and replacing raw object SDKs with intelligent Fastio API tool calls. This guide walks through the complete migration process, from assessing your current storage topology to updating agent code to use Fastio MCP tools or REST APIs. You'll learn how to sync existing files, restructure data into workspaces, and use built-in RAG capabilities that eliminate the need for separate vector databases.
How to Migrate AI Agent File Storage: The Complete Guide
Agent file storage migration moves AI agent data, outputs, and workspaces between storage systems without disrupting production workflows. This guide provides a complete five-phase migration plan with rollback strategies for AI agent systems requiring persistent state. Most teams migrate storage within their first year, with migrations typically taking several weeks for production systems.
How to Optimize RAG Retrieval for Autonomous Agents
Optimizing RAG for agents involves tuning chunk sizes and retrieval strategies to provide actionable context for reasoning, not just summarization. This guide covers hybrid search, reranking, and agentic workflows to boost performance by up to 48%.
How to Orchestrate Pydantic AI Agents in a Shared Workspace
Orchestrating AI agents requires more than just code; it needs a coordination layer where distributed teams can synchronize state and dependencies. A shared workspace for Pydantic AI allows developers to maintain consistent validation schemas and agent states across a collaborative environment. By integrating structured outputs with a shared file store, teams can accelerate development cycles and ensure that multi-agent systems behave predictably in production.
How to Perform RAG with Large Files: Strategies for Heavy Documents
Retrieval Augmented Generation (RAG) on large files requires smart chunking, indexing, and retrieval strategies to avoid context window overflows.
How to Point AI Agents at Google Files: APIs vs. Agent Rooms
Exposing Google Files to AI agents requires dynamic document conversion into LLM-friendly formats like markdown and caching in a shared workspace. Developers typically choose between direct API integration and collaborative Agent Rooms. While raw APIs offer low-level control, they introduce parsing overhead and OAuth complexity. This guide explains how to use Fastio to import, index, and securely expose documents to developer agents.
How to Save and Persist Code Interpreter Files Beyond the Session
Code interpreters run your Python in a sandbox, but every file vanishes when the session ends. This guide explains where code interpreter files actually live, why they disappear, and how to persist them using external workspace storage so your outputs survive between sessions.
How to Scale AI Agent Storage: Strategies and Solutions
AI agent storage scaling ensures performance under growing data loads from multiple agents. As agent teams handle more files, uploads, queries, and shares, basic storage fails without proper strategies. This guide covers challenges, a scaling checklist, and Fastio features like a consolidated MCP toolset, advisory file locks, and version history for concurrent access.
How to Secure Vector Stores for AI Agents
Vector stores are the memory layer for AI agents, and attackers know it. RAG poisoning, embedding manipulation, and cross-tenant data leaks can silently corrupt agent behavior. This guide covers the attack surface, practical defenses, and how to implement multi-agent access controls that most vector databases still lack.
How to Set Up a Llama Agent Workspace
Llama agent workspaces combine persistent storage, RAG, and collaboration for AI agents running Llama models. Fastio plans start at $29/month with 5 seats, 1 TB of storage, and 300,000 monthly credits, and every organization begins with a 14-day trial. This step-by-step guide walks you through setup from account creation to multi-agent workflows.
How to Set Up a Self-Hosted AI Agent Workspace
A self-hosted AI agent workspace runs entirely on local infrastructure. It provides privacy-focused storage and tool access for AI agents without relying on cloud providers. This guide walks through hardware requirements, software stack, and detailed setup steps. You will learn to handle key challenges like multi-agent file locking and scaling. While self-hosting offers control, it comes with maintenance burdens. Managed services address these gaps with built-in features.
How to Set Up Agentic AI Storage for Persistent Agent Memory
Agentic AI storage provides persistent file and data access that autonomous agents need to complete multi-step tasks across sessions. This guide covers storage architecture patterns, compares vector databases to file storage, and walks through setting up persistent memory for production agent systems.
How to Set Up AI Agent Blob Storage for Tool Calling
Blob storage gives AI agents a place to save tool outputs and state reliably. Chatbots can only hold short conversations in memory, but agents running multi-step tasks need storage for workflows, outputs, and memory between runs. Fast. This guide shows why generic storage falls short for agents, production features you need, and step-by-step setup for Fastio workspaces with the 14-day Business Trial.
How to Set Up AI Agent Dagster Storage
AI agent Dagster storage persists pipeline assets, run logs, and agent state across executions. Dagster orchestrates complex AI workflows, but effective storage ensures reliability and scalability. Fastio provides MCP-compatible persistence with generous storage, built-in RAG, and a consolidated MCP toolset for dagster agent persistence and dagster pipelines agents.
How to Set Up AI Agent Game Asset Workspaces
AI agent game asset workspaces store textures, models, and other files for game development. Agents and humans use these shared spaces to manage large projects, handle files over multiple, and track versions. Game developers use them to automate tasks like optimization and to work with engines like Unity. This guide shows you how to set one up and connect it to your tools.
How to Set Up an Agentic Team Workspace
Agentic team workspaces enable human-agent hybrid collaboration with shared intelligence and persistent storage. While most cloud storage tools focus on human users, modern AI agents require API-first environments with built-in RAG and semantic search. This guide explains how to set up a dedicated workspace where your agents can build, store, and hand off work to human team members, starting with generous storage.
How to Set Up an AI Agent Blockchain Workspace
An AI agent blockchain workspace is shared storage that lets AI agents test smart contracts, run simulations, and maintain persistent state across sessions. Blockchain developers use these workspaces to collaborate on chain data, transaction logs, and deployment scripts without losing work between runs. This guide walks through setting up a Fastio workspace optimized for blockchain AI agents.
How to Set Up an AI Agent Shared Workspace
A shared workspace gives multiple AI agents a single place to read, write, and organize files without stepping on each other's work.
How to Set Up an AI Agent Workspace
An AI agent workspace is a dedicated environment where autonomous agents can store files, maintain state, and organize their work, similar to how humans use project folders and cloud storage. While most agents operate with ephemeral memory, giving them a persistent workspace unlocks complex, long-running workflows.
How to Set Up Chroma Storage for AI Agents
AI agent chroma storage uses Chroma DB as an embedded vector database for local RAG without cloud dependencies. It stores embeddings and documents right on the agent's local machine or container for fast retrieval during inference. Chroma handles indexing, querying, and persistence for agent memory and knowledge bases. Agents can add documents, query similar content, and update collections dynamically. Local setups cut network latency.
How to Set Up CodeSandbox AI Agent Storage
CodeSandbox AI agent storage bridges ephemeral sandboxes to persistent workspaces. Agents in CodeSandbox need reliable file persistence for iteration and multi-run workflows. Fastio provides generous storage with MCP tools for smooth integration. CodeSandbox hosts 4 million developers monthly and offers SDK for programmatic sandboxes. However, built-in storage resets on inactivity, limiting agent use cases. This how-to covers why persistence matters, Fastio features, and step-by-step setup.
How to Set Up File Storage for Grok xAI Agents
Grok agents from xAI need file storage that holds data across sessions for tool use. Fastio workspaces offer API access and AI tools like RAG. This guide shows setup, features, and workflows.
How to Set Up File Storage for n8n AI Workflows
n8n AI workflows need persistent file storage to save documents, process AI outputs, and build RAG pipelines. This guide shows you how to set up cloud storage, handle binary data, and connect file operations with AI nodes.
How to Set Up File Storage in Flowise
Flowise is a drag-and-drop UI for building LLM-powered applications, but it doesn't include persistent file storage out of the box. This guide walks through setting up a custom tool node in Flowise that connects to Fastio, giving your chatflows the ability to save, retrieve, and share files as part of automated AI workflows.
How to Set Up High Availability Storage for AI Agents
AI agent high availability storage keeps workflows going during failures or maintenance. Agents rely on steady access to files, state, and tools; downtime stops data processing or multi-agent coordination dead. Standard storage misses key agent needs like concurrent access or reactive updates. This guide covers what's needed, main features, provider comparisons, and setup steps for production-ready systems.
How to Set Up Persistent Storage for AutoGPT
Persistent storage lets AutoGPT save task memory and files between runs. Otherwise, agents forget everything and stick to simple tasks. This guide covers local setups and cloud options like Fastio, ready for real-world use.
How to Set Up Storage for Agent Testing Environments
Agent testing environment storage provides isolated workspaces for developing, testing, and staging AI agents before production deployment. This guide walks through setting up separate storage layers for dev, staging, and production agent environments, with practical patterns for test data, access controls, and promotion workflows.
How to Set Up Synced File Workspaces for AI Agents
Synced file workspaces keep files current for AI agents across runs and teams. Without good sync, agents re-download files, miss updates from others, and lose past context. This guide reviews three sync methods (failures cause 25% of agent errors) and RAG setup.
How to Store AI Agent Reasoning Traces for Debugging and Review
Reasoning trace storage captures an AI agent's step-by-step thought process, tool-call decisions, and intermediate outputs in persistent, queryable files. This guide covers why ephemeral observability is not enough, how to structure traces for long-term retrieval, and practical approaches to storing them so your team can debug failures and review agent behavior weeks or months after the fact.
How to Store CI/CD Build Artifacts Using the Fastio API
This Fastio API guide shows you how to works alongside platforms like GitHub Actions and GitLab CI. Adding the Fastio API to your CI/CD pipelines gives you scalable, globally distributed storage for build artifacts and deployment logs. Learn how to bypass native storage limits and give AI agents access to your build data.
How to Store Legal Contracts for AI Analysis Agents
Legal contract analysis agents need secure, version-controlled storage to review and compare documents. This guide explains the architecture you need to support autonomous legal agents while keeping strict security standards.
How to Use AI Agent Knowledge Graph Storage
Knowledge graph storage for AI agents acts as a structured data layer that lets agents understand connections between entities. Unlike basic file storage, it maps relationships to prevent hallucinations and improve context. This guide explores how to implement graph storage, compares top databases, and explains why connected memory is essential for autonomous workflows.
How to Use AI Agent Prompt Caching to Reduce LLM Costs and Latency
AI agent prompt caching stores and reuses prompt prefixes, system instructions, and context windows to avoid redundant token processing. This method reduces API costs by up to multiple% and cuts response latency by multiple% for repeated operations. By improving how agents send instructions and background data, developers can build faster, more affordable AI systems.
How to Use AI Agent Workspaces for Manufacturing Teams
AI agent manufacturing workspaces enable production agents and human engineers to access CAD files, logs, and supply chain documents in a shared, intelligent environment. Unlike traditional cloud storage, these workspaces support the specific needs of modern factories: version-tracked file access and granular permissions, automated RAG indexing for technical queries, and smooth handoffs between autonomous agents and human experts.
How to Use AutoGen Memory: Managing State in Microsoft's Agent Framework
AutoGen memory lets agents remember conversation history and learned facts across runs, creating "teachable" agents. By default, Large Language Models (LLMs) are stateless. They forget everything once a session ends. AutoGen solves this with the `TeachableAgent` class and vector database integration, so agents can recall user preferences, past decisions, and specific instructions indefinitely.
How to Use Qdrant for AI Agent Storage
AI agent Qdrant storage enables efficient vector similarity search in agentic workflows. Qdrant stores embeddings from agent actions, tool outputs, and documents for semantic retrieval. This guide covers setup, MCP integration, comparisons with Milvus, and pairing with Fastio workspaces for complete agent memory. Agents need persistent memory beyond LLM context windows. Qdrant handles billions of vectors with low latency using HNSW indexing.
How to Use Supabase Storage for AI Agents
Supabase provides an open-source backend that combines a Postgres database, file storage, and real-time updates into a single layer for AI agents. This guide explains how to set up the infrastructure your agents need to stay persistent, manage shared files, and build long-term memory. You will learn the strengths and limits of using Supabase for these workflows and see when a more agent-centric tool like Fastio might be better for your project.
How to Use WebDAV Storage for AI Agents
AI agent WebDAV storage uses HTTP extensions for reliable file access in self-hosted environments. Agents read, write, and lock files directly over standard WebDAV endpoints. This guide covers server setup, agent integration, permissions, and why MCP tools offer a modern upgrade.
Local vs Cloud Storage for AI Agents: A Complete Comparison
Local storage gives AI agents lower latency and full data control, but cloud storage cuts DevOps time and scales without hardware limits. This guide breaks down the tradeoffs across cost, performance, security, and maintenance so you can pick the right architecture for your agents.
Proxemics in Communication: Designing Shared Context for AI Agents
Applying proxemics in communication to multi-agent workspaces offers a systematic framework for structuring agent folders, context boundaries, and shared database views. By mapping physical distance concepts to directory levels, developers can increase context retrieval speeds and reduce context window tax. This guide details how spatial proximity and filesystem layout govern context organization for AI teams.
RAG Architecture: Storage Strategies for Document Retrieval
RAG storage architecture encompasses the document store, vector database, and file management layer that power retrieval-augmented generation systems. This guide explains how to design each component for accuracy, performance, and cost efficiency.
Setting Up Claygent File Storage: How to Store AI Research Assets
B2B contact data decays at a rate of 22% to 35% annually, forcing sales operations teams to waste up to 30% of their prospecting hours manually verifying records. Automating lead enrichment with Claygent solves the manual bottleneck, but requires a structured file storage layer. This guide covers how to set up Claygent file storage to optimize your AI research workflows.
Storage Integration for AI Agent Builder Platforms
AI agent builder platforms need storage integration to persist data, access documents, and deliver outputs. This guide covers how top platforms handle storage, what to look for when evaluating options, and how to implement reliable file access for your agents.
The Ultimate Company Brain Setup Checklist for Teams and Agents
Learn how to build a unified knowledge base using this practical company brain setup checklist. Connect team repositories via cloud import, configure metadata views, set up permissions, and link agents using the Fast.io MCP server.
Top 10 Cloud Storage APIs for AI Applications
A cloud storage API for AI is a programmatic interface that lets AI applications store, retrieve, and manage files and data in the cloud without managing infrastructure. This guide evaluates leading cloud storage APIs for AI workloads like agent artifacts, RAG document stores, model outputs, and more, with practical examples.
Top 7 AI Workspaces for Architecture Agents in 2026
Top AI workspaces for architecture agents let AI handle BIM modeling, site planning, and design reviews. These platforms support agentic workflows in architecture, engineering, and construction (AEC), but few offer true multi-agent BIM sharing. According to ENR, 16% of A/E firms use generative AI on projects, creating demand for better agent tools.
Top 7 Vector Database Alternatives for AI Agents (2026)
Guide to top vector database alternatives: Vector databases serve as the long-term memory for AI agents, storing semantic embeddings that allow models to retrieve context, history, and knowledge. While the market is projected to reach $2 billion by 2027, developers often face a difficult choice between managed services like Pinecone, open-source powerhouses like Weaviate, or integrated solutions that handle indexing automatically. This guide compares the top options based on latency, cost, and d
Top RAG Storage Backends for AI Applications
RAG adoption surged as developers rushed to use private data with AI models. Choosing the right backend matters. We review the top RAG storage solutions, from specialized vector databases to integrated platforms that handle the entire file pipeline.
Top Tools for RAG Evaluation: Measuring Agent Performance
Retrieval-Augmented Generation (RAG) systems can fail silently, serving confident but incorrect answers. To build reliable agents, you need reliable evaluation pipelines. This guide compares the top tools for RAG evaluation, including Ragas, TruLens, and DeepEval, to help you measure context precision, faithfulness, and answer relevance.
What Documents Belong in a Company Brain? An Ingestion Playbook
A company brain is a digital repository containing an organization's core intellectual property, processes, product specs, legal agreements, and meeting transcripts, optimized for AI retrieval. Ingesting the right assets transforms passive documents into queryable assets, but standard vector databases struggle with raw files. This playbook details the exact documents to ingest, the formatting rules for clean ingestion, and how to build structured metadata schemas for legal and financial files.
Zero Retention Workspaces for AI Agents: A Practical Guide
A zero retention workspace gives AI agents a place to read, write, and process files without leaving file content behind once the task is done. This guide covers what zero retention means for agent workspaces (not LLM inference), how ephemeral workspaces fit into enterprise AI rollouts, and how to implement one without losing the audit trail you need for compliance reviews.