Agent File and Document Workflows
What happens to files once an agent is in the loop. These pages cover ingestion and classification, document processing and extraction, versioning and lineage, permissions on generated output, batch operations, and the handoff to a human who needs to review the result. This is the part of agent work that fails quietly, because an agent that produces good output nobody can find has not finished the job. Fast.io keeps full version history and citation-backed search across the files it holds.
The pages cover the boring parts deliberately: naming and structure that survive contact with other people, permissions that outlast whoever set them, and the record that answers what happened three months later. Where an agent generates output for a client or a colleague, they carry on past the file being written to the part where somebody else opens it, which is where these workflows usually break.
183 guides in this topic.
Start here
How to Extract Metadata from YouTube Videos
YouTube video metadata includes title, description, tags, view counts, thumbnails, and dozens of other structured fields. This guide covers four practical ways to extract that data: the YouTube Data API v3, the yt-dlp command-line tool, custom Python scripts, and browser-based viewers.
7 Best Batch Metadata Editing Tools in 2026
Batch metadata editing software lets you modify embedded file properties like titles, dates, tags, and copyright across hundreds or thousands of files in a single operation. This guide compares seven tools that handle bulk metadata workflows, from free command-line utilities to AI-powered cloud platforms, so you can pick the right one for your file types and team size.
How to Extract File Metadata with PowerShell on Windows
PowerShell ships with every Windows 10 and 11 machine, making it the fastest way to read file metadata without installing anything. This guide covers four approaches, from Get-ItemProperty for basic timestamps to Shell.Application COM objects that expose over 300 extended properties, System.Drawing for image EXIF data, and recursive scripts that process entire folder trees into CSV reports.
Best Document Processing Tools for AI Agents
Document processing tools for AI agents automate the extraction, parsing, and transformation of unstructured documents (PDFs, images, contracts) into structured data that agents can act on. This guide reviews leading platforms across OCR engines, parsing APIs, extraction tools, and end-to-end IDP solutions optimized for AI workflows.
7 Best Free Online File Metadata Viewers
A hands-on comparison of seven free browser-based metadata viewers. Each tool is tested for format support, file size limits, and privacy approach, so you can pick the right one for inspecting photos, documents, and video files without installing anything.
How to Extract GPS, Altitude, and Flight Data from Drone Photos
Drone photos contain far more metadata than standard camera images. Beyond GPS coordinates, they embed relative and absolute altitude, gimbal orientation, flight attitude, and manufacturer-specific telemetry. This guide covers how to extract that data from DJI, Autel, and Skydio images using ExifTool and programmatic methods, plus how to reconstruct flight paths from photo sequences.
All guides
7 Best Batch Metadata Editing Tools in 2026
Batch metadata editing software lets you modify embedded file properties like titles, dates, tags, and copyright across hundreds or thousands of files in a single operation. This guide compares seven tools that handle bulk metadata workflows, from free command-line utilities to AI-powered cloud platforms, so you can pick the right one for your file types and team size.
7 Best Free Online File Metadata Viewers
A hands-on comparison of seven free browser-based metadata viewers. Each tool is tested for format support, file size limits, and privacy approach, so you can pick the right one for inspecting photos, documents, and video files without installing anything.
8 Best AI Spreadsheet Automation Tools for Agents in 2026
AI spreadsheet automation tools let agents programmatically read, transform, and generate spreadsheet data using natural language or API calls instead of manual formulas. This guide covers 8 tools evaluated for agent-readiness, from MCP-native platforms to API-first add-ins, with pricing and integration details for each.
AI Agent File Lineage Tracking: A Practical Guide
File lineage tracking records which agents touched a file, when, and what they changed, so downstream agents and humans can trace outputs back to their source. This guide covers what to capture, how to model events, and how to wire lineage into a multi-agent pipeline without slowing it down.
AI Agent File Permissions: How to Control What Agents Can Read, Write, and Share
AI agent file permissions define what files an autonomous agent can read, write, delete, or share, using role-based or attribute-based access controls to prevent unauthorized data access and enforce least-privilege principles. This guide covers how to secure agentic workflows through sandboxing, per-task scoping, and granular access levels.
AI Document Processing Agents: A Developer Guide
AI document processing agents automatically read, understand, extract, and transform information from PDFs, images, and scanned files. This guide covers how they work, what they can process, and how to integrate persistent storage for extracted data.
Best AI Document Summarization Tools in 2026
AI document summarization tools differ wildly in how they handle long PDFs, legal contracts, and academic papers. After reviewing results from Fritz AI's 8-tool benchmark, Lindy AI's 20-tool comparison, and AI Lawyer Pro's legal-focused evaluation, this guide ranks the 10 best summarizers by what they actually do well and where they fall short.
Best AI File Organizers in 2026: 8 Tools That Actually Sort Your Files
McKinsey estimates that employees spend 1.8 hours every day just searching for and gathering information. AI file organizers attack that problem by reading file contents, applying tags, renaming documents, and routing them into the right folders automatically. This guide covers eight tools across desktop, cloud, and hybrid platforms, with honest evaluations of what each does well and where it falls short.
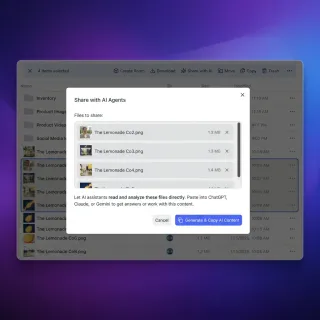
Best AI-Powered Document Management Systems
An AI-powered document management system uses artificial intelligence to automatically classify, tag, search, summarize, and organize documents. The best platforms combine semantic search with auto-summarization and extraction that goes beyond traditional keyword matching. We evaluated ten leading platforms based on their AI capabilities, ease of use, and pricing.
Best Document Processing Tools for AI Agents
Document processing tools for AI agents automate the extraction, parsing, and transformation of unstructured documents (PDFs, images, contracts) into structured data that agents can act on. This guide reviews leading platforms across OCR engines, parsing APIs, extraction tools, and end-to-end IDP solutions optimized for AI workflows.
Best File Sharing for Fine-Tuning AI Datasets
Guide to file sharing fine tuning datasets: Fine-tuning an LLM starts long before you write a training config. You need to collect, clean, version, and distribute datasets across your team and your agents. This guide compares the most common ways to share private fine-tuning datasets and explains where each option fits in a real ML pipeline.
Best OCR Tools for AI Agents: Vision-to-Text APIs for Developers
OCR tools for AI agents use computer vision to extract text from images, scans, and handwritten notes, feeding the result into LLMs for analysis or action. Modern AI-based OCR reaches 99%+ character accuracy, with handwritten text extraction improving by 40% through multimodal models. This guide compares traditional OCR, LLM-native vision, and specialized APIs.
Best Secure File Sharing for AI Teams in 2026
AI teams face unique security challenges when sharing sensitive training data, proprietary model weights, and research outputs. This guide evaluates the best secure file sharing platforms based on encryption strength, large file support, access controls, and API integration for ML workflows.
Best Social Media Metadata Extraction API Tools for 2026
Social media metadata extraction tools pull structured data from posts, profiles, and shared links across platforms like X, Instagram, TikTok, and LinkedIn. This guide compares seven tools across three extraction approaches, with pricing, rate limits, and data quality tradeoffs for each.
ChatGPT File Upload Limits: How to Handle Large Files and Folders
ChatGPT limits file uploads to 512MB per file with total storage limits per user, creating problems for large datasets.
Converting std::filesystem::path to String in C++ (Cross-Platform)
Converting a C++ filesystem path to a string portably requires addressing operating system encoding differences and language updates. C++20 introduces char8_t string types for UTF-8 paths, breaking compatibility with older narrow string APIs. Understanding how to handle these type changes and native wide-character paths on Windows ensures cross-platform agents can exchange paths without data corruption.
Distributed File System Architectures for Multi-Agent Collaboration
Coordinating parallel autonomous AI agents requires moving beyond isolated containers. This guide examines how distributed file system architectures provide a shared, versioned storage substrate to maintain consistency and prevent state corruption in multi-agent environments.
Docker File Server vs. Agent Rooms: Persistent Storage for Sandboxed Agents
Self-hosting a Docker file server for containerized coding agents requires managing port forwarding, custom permission models, and volume backups. In contrast, cloud-hosted Agent Rooms connect sandboxed agents with zero networking configuration using a remote Model Context Protocol endpoint. This article compares the two storage approaches, highlighting the RAG indexing, webhook event streams, and version controls needed for autonomous developer workflows.
Dublin Core vs XMP vs IPTC: Choosing the Right Metadata Standard
Dublin Core, XMP, and IPTC each solve a different metadata problem. Dublin Core catalogs resources across libraries and archives, XMP embeds extensible metadata inside file formats, and IPTC describes the content and rights of photographs. This guide compares all three standards head to head, maps each to its strongest use cases, and explains how they overlap inside the same file.
Embedded Metadata vs Sidecar Files: Which XMP Approach to Use
Embedded metadata lives inside the file itself, while sidecar files store metadata externally in a companion .xmp file. Each approach has real tradeoffs around portability, file integrity, format compatibility, and workflow complexity. This guide compares them head to head and provides a decision framework based on your file formats, sharing needs, and preservation goals.
Fastio Event Feeds: A Guide to Real-Time File Events
Fastio enables developers to trigger AI agents or human workflows instantly when files are added, modified, or deleted in a workspace. Real-time WebSocket event feeds and activity polling eliminate inefficient short-polling and power responsive event-driven architectures.
GitHub File Size Limits Explained for Teams and Copilot
GitHub hard-blocks any single file larger than 100 MiB in normal Git history, warns above 50 MiB, and caps browser uploads at 25 MiB. Those thresholds are why model weights, datasets, and agent build artifacts break pushes long before a repository feels "large." This guide maps the official caps, shows how to fix a rejected push, and helps you choose Git LFS, Releases, object storage, or a shared workspace when GitHub Copilot and human teammates need big files outside the repo.
How to Add File Watermarking to Your AI Agent Pipeline
AI agent file watermarking is the automated process of embedding visible or invisible identifiers into documents, images, or videos before an agent shares them with recipients. This guide walks through watermarking types, how to build watermarking into an agentic delivery pipeline, and how to trace leaks back to specific recipients when something goes wrong.
How to Automate Document Processing with AI Agents
AI agent document processing uses autonomous agents to extract, analyze, and transform information from documents without manual intervention. Unlike traditional OCR, these agents can reason about content, handle unstructured data, and execute complex workflows. This guide shows you how to build agent pipelines that process documents quickly and accurately.
How to Automate File Classification with AI Agents
AI agent file classification automation uses intelligent agents to categorize incoming documents, apply tags, and route them to the right storage locations without human intervention. This guide walks through the full pipeline, from ingestion to verification, and shows how to wire it up with workspace routing and granular permissions that most classification guides skip.
How to Automate File Unzipping on macOS inside Agent Workspaces
Automating how you unzip files on Mac workspaces allows autonomous AI agents to process compressed archives. Using terminal utilities like ditto or unzip in automated script execution avoids execution failures.
How to Automate PDF Report Generation with AI Agents
AI agent PDF report generation is the process of autonomous agents creating, formatting, and delivering PDF documents from data analysis, research findings, or business workflows without human intervention. By replacing manual compilation with intelligent automation, enterprises can save significant time annually while improving report accuracy and consistency.
How to Automate Share Link Revocation for AI Agents
AI agents generate share links at machine speed, and every link that outlives its purpose is a potential leak. This guide covers four automation triggers for revocation, how to wire them up with event feeds and scheduled jobs, and how Fastio fits into an event-driven share lifecycle.
How to Automate Spreadsheets with AI Agents
Manual data entry takes up nearly 30% of the work week. AI agents take over these repetitive tasks by reading, updating, and creating spreadsheets autonomously. Unlike Excel plugins that require your active attention, these agents process thousands of rows in the background. This guide shows you how to build a fully automated pipeline where agents pull files from storage, transform the data, and deliver clean reports.
How to Automate the Fastio API Metadata Extraction Workflow
The Fastio metadata extraction workflow automatically processes uploaded files, pulling out important EXIF data, text summaries, and structural attributes to feed directly into agent memory. This capability lets developers build context-aware AI agents without relying on third-party parsing libraries for many common file types. Knowing how to map this structured data keeps your intelligent workspace organized and performant.
How to Automatically Organize and Sort Files Using Metadata
Most file organization systems rely on manual folder structures that break down as libraries grow. Metadata-based organization uses properties already embedded in your files, like creation dates, camera models, and document authors, to sort them automatically. This guide covers practical tools and scripts for building metadata-driven file workflows, from single ExifTool commands to AI-powered extraction at scale.
How to Build a Document Processing Pipeline with Fastio API
A document processing pipeline built on the Fastio API listens for new file uploads, automatically routes them for AI extraction, and stores structured metadata back in the workspace. This guide walks through each stage, from workspace setup and event listening to LLM-powered extraction and metadata tagging, with practical code examples you can adapt for invoices, contracts, and forms.
How to Build a File Sharing Portal with Fastio API
Building a custom file sharing portal gives your team control over the user experience without managing backend storage. A custom portal uses the Fastio API as the storage engine while you design the interface. This guide covers how to create a fast and secure client portal, handle authentication, and add AI agent integrations directly.
How to Build a Metadata Governance Framework That Actually Works
A metadata governance framework defines the policies, roles, standards, and processes an organization uses to keep metadata accurate, consistent, and discoverable across all data assets. This guide walks through the seven pillars of effective metadata governance, common implementation pitfalls, and how automation tools can reduce the manual burden of keeping metadata clean.
How to Build AI Data Extraction Agents That Store and Organize Results
AI data extraction agents are autonomous systems that identify, extract, and structure data from websites, documents, and databases without predefined templates. This guide covers how they work, the main technologies behind them, and the part most guides skip: how to store, organize, and query your extracted data so it actually becomes useful.
How to Build an Agentic File Router with Fastio Events
An agentic file router uses Fastio realtime events to dispatch uploaded files to specialized AI agents based on metadata or content type. Connecting event payloads directly to LLM context windows reduces processing latency and helps you build reactive multi-agent systems. This guide shows you how to build a router that evaluates incoming files and hands them off to the right agent for the job.
How to Build an AI Agent Delivery Portal
Most AI agent guides stop at "save to disk," leaving a gap between agent output and the humans who need it. A delivery portal bridges that gap by giving agents a secure, white-labeled destination to deposit completed work for clients, teammates, or stakeholders. This guide walks through building one with Fastio's share system, covering password protection, expiration controls, and guest access.
How to Build an AI Agent Document Redaction Pipeline
AI agent document redaction automation uses an autonomous agent to detect and remove sensitive information like names, SSNs, and account numbers from documents without manual review. This guide walks through building a five-stage redaction pipeline, from document ingestion to verified delivery, and explains how to connect it to a workspace where humans can review the output.
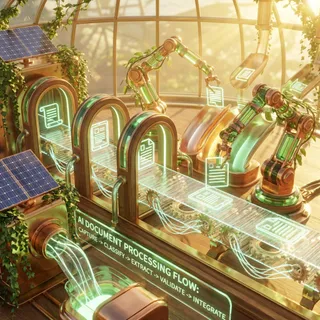
How to Build an AI Document Processing Workflow
An AI document processing workflow automates the ingestion, extraction, validation, and routing of documents using machine learning models. This guide covers practical architectures from OCR to agentic workflows, including storage integration and delivery patterns.
How to Build an AI File Manager with the Fastio API
Most AI agent tutorials skip the hardest part: giving your agent reliable, searchable file storage that works across sessions. This guide walks through building a complete AI file manager on the Fastio API, from authentication and uploads to semantic search and ownership transfer.
How to Build Automated Metadata Extraction Webhook Workflows
Polling for new files wastes compute and delays processing. Webhook-driven metadata extraction pipelines react to file events in real time, pulling structured data from documents, images, and media the moment they arrive. This guide walks through building these pipelines with storage event feeds, n8n, and custom Node.js handlers.
How to Build Base44 Metadata Views for Document Extraction
Base44 metadata views automatically parse file attributes to populate structured database tables and search filters. Extracting document properties into typed fields allows developers to build responsive UI components, eliminate manual data entry, and simplify file workflows across web applications.
How to Build Concurrent File Uploads with the Fastio API
Handling massive data ingestion for AI agents requires more than just standard file transfer protocols. This guide explains how to implement concurrent file uploads using the Fastio API to maximize throughput. You will learn how to build connection pools, balance high concurrency against enterprise rate limits, and ensure reliable data delivery for multi-agent systems.
How to Build Multi-Agent File Annotation Workflows
Manual data annotation is a bottleneck for AI development. Multi-agent file annotation allows parallel labeling with conflict resolution, speeding up workflows. By using specialized agents for different data types and a coordination layer like Fastio, teams can process thousands of files simultaneously without overwriting each other's work.
How to Choose a File Conversion API for AI Agents
AI agents often hit a wall when they encounter proprietary file formats like PDF, DOCX, or PSD. A file conversion API bridges this gap, allowing agents to transform unreadable binary data into text or standard formats they can process. This guide explores the best APIs for agentic workflows and introduces a zero-conversion alternative.
How to Compare Documents with AI Agents
Traditional diff tools show you what changed between two documents. AI agents go further, comparing meaning, flagging risk, and producing structured reports that teams can act on. This guide walks through how AI agent document comparison works, what to look for in a comparison pipeline, and how to build one that delivers results to the right people.
How to Configure FileZilla SFTP Server for AI Agent Workspaces
Setting up FileZilla Pro Enterprise Server for secure SFTP access allows developers to expose local directories to containerized AI agents. By hardening directory permissions, disabling file deletion, and utilizing SSH public keys, teams can build secure local workspaces. This guide explains how to configure FileZilla listeners, restrict user folder permissions, and connect agent tools to Fast.io workspaces.
How to Connect AI Agents to Files and Cloud Storage
Connecting AI agents to files is the practical bottleneck most developers hit after getting their agent logic working.
How to Coordinate AI Agents: Google Drive Shared Folders vs. Agent Rooms
Exposing shared directories to autonomous AI agents requires instant synchronization, granular permissions, and detailed version history. Traditional human-centric platforms like Google Drive introduce severe latency and lack context for parallel LLM executions. Using a dedicated agent room workspace resolves these challenges by introducing webhooks for sub-second event propagation, built-in semantic search, and structured metadata extraction via Metadata Views.
How to Create AI Agent Testing File Fixtures
Testing file fixtures provide consistent, versioned test data for validating AI agent behavior across different scenarios. Without reliable fixtures, random LLM responses and non-deterministic tool usage can make debugging file operations impossible.
How to Create Branded Client Portals with Fastio API
Guide to creating branded client portals with fast api: The Fastio API lets developers build branded, secure client portals for delivering agent-generated files to human users. Building these programmatic workspaces removes manual email attachment workflows and creates customized handoff links instantly.
How to Debug AI Agent File Access Issues
File access errors are a leading cause of agent failures. These turn automated workflows into broken pipelines. This guide shows how to fix permission conflicts, stop API timeouts, decode error codes, and set up reliable storage.
How to Design a Metadata Extraction Pipeline
A metadata extraction pipeline takes raw files and turns them into structured, queryable data. Getting the architecture right means choosing the correct queue topology, routing files to format-specific workers, normalizing output schemas, and handling failures without losing data. This guide walks through each design decision with concrete implementation patterns.
How to Detect AI-Generated Images Using Metadata
AI-generated image metadata detection uses embedded file properties like IPTC DigitalSourceType, EXIF software tags, and C2PA manifests to identify whether an image was created by generative AI tools. This guide covers how each major generator marks its output, the practical tools for reading those markers, and what to do when metadata has been stripped.
How to Edit and Extract ID3 Tag Metadata from Music Files
ID3 tags are metadata containers embedded in audio files that store artist, album, track number, genre, album art, and other descriptive fields. This guide walks through the differences between ID3 tag versions, how to edit tags with desktop tools like Mp3tag, and how to read and write metadata programmatically using Python and Node.js libraries.
How to Edit and Extract XMP Metadata from Any File
XMP (Extensible Metadata Platform) is the ISO standard for embedding structured metadata in files like PDFs, images, and video. This guide covers what XMP metadata is, how it differs from EXIF and IPTC, and walks through the best free and professional tools for editing and extracting it, including batch workflows and DAM integration.
How to Extract and Verify C2PA Content Credentials
C2PA Content Credentials are cryptographically signed manifests that record an asset's origin, edits, and provenance chain. This guide covers extracting manifests with c2patool CLI, reading them programmatically with the JavaScript SDK, verifying signatures against trust lists, and comparing C2PA to traditional EXIF metadata.
How to Extract Document Metadata with Large Language Models
Large language models can read unstructured documents and return structured metadata fields like author, date, topic, and entity tags without hand-coded rules. This guide covers how to prompt LLMs for reliable extraction, catch hallucinated fields, compare costs against traditional parsers, and build a production pipeline.
How to Extract File Metadata for Digital Forensics Investigations
Digital forensic metadata extraction is the process of systematically recovering and preserving embedded file properties as evidence, maintaining chain of custody and data integrity for legal proceedings. This guide covers the types of metadata relevant to investigations, forensically sound extraction workflows, the tools practitioners use, and how to keep extracted data admissible in court.
How to Extract File Metadata with C# and .NET Libraries
C# has several mature libraries for reading metadata from files, each targeting different formats. This guide compares MetadataExtractor for images, TagLib# for audio, iText7 for PDFs, and built-in .NET APIs for basic file properties. You will learn how to install each library, write extraction code, handle cross-platform pitfalls, and build a metadata pipeline that works in ASP.NET and Azure Functions.
How to Extract File Metadata with JavaScript and Node.js
JavaScript and Node.js metadata extraction libraries let developers read embedded file properties like EXIF tags, ID3 audio tags, and PDF document info directly in server-side or browser-based applications. This guide compares the five most popular libraries, walks through code examples for each file type, and covers how to handle metadata extraction at scale without writing custom parsers.
How to Extract File Metadata with PHP Libraries
PHP ships with built-in EXIF and IPTC functions that most other languages lack, and its ecosystem includes mature libraries like getID3 and smalot/pdfparser for audio, video, and document metadata. This guide walks through each option with working code, covers format-specific gotchas, and shows how to build a metadata extraction pipeline that handles mixed file types in production.
How to Extract File Metadata with PowerShell on Windows
PowerShell ships with every Windows 10 and 11 machine, making it the fastest way to read file metadata without installing anything. This guide covers four approaches, from Get-ItemProperty for basic timestamps to Shell.Application COM objects that expose over 300 extended properties, System.Drawing for image EXIF data, and recursive scripts that process entire folder trees into CSV reports.
How to Extract File Metadata with Python Libraries
Python has more than ten mature libraries for reading metadata from files, each specialized for different formats. This guide compares the leading options, from Pillow for image EXIF data to pypdf for PDF properties, Mutagen for audio tags, and pymediainfo for video streams. You will learn how to install each library, write extraction scripts, and build a pipeline that handles mixed file types at scale.
How to Extract Geolocation Metadata from Photos
Every photo your smartphone takes embeds GPS coordinates accurate to a few meters. This guide covers how to read that geolocation data, extract it in bulk from hundreds of photos, convert coordinates to street addresses, and manage location metadata across teams and platforms.
How to Extract GPS, Altitude, and Flight Data from Drone Photos
Drone photos contain far more metadata than standard camera images. Beyond GPS coordinates, they embed relative and absolute altitude, gimbal orientation, flight attitude, and manufacturer-specific telemetry. This guide covers how to extract that data from DJI, Autel, and Skydio images using ExifTool and programmatic methods, plus how to reconstruct flight paths from photo sequences.
How to Extract Metadata for AI Training Datasets
Metadata extraction for AI training datasets is the process of programmatically reading file properties, format details, dimensions, duration, creation dates, and labels, then assembling that information into structured manifests that govern dataset composition and provenance. This guide walks through building extraction pipelines, choosing the right metadata fields, meeting regulatory requirements like the EU AI Act, and using workspace tools to manage training data at scale.
How to Extract Metadata for Content Migration Projects
Content migration metadata extraction is the process of pulling structured properties like titles, tags, categories, authors, dates, and permissions from a source system and mapping them to the target platform's schema so that content retains its organization and discoverability after migration. This guide covers auditing source metadata, building field mapping documents, handling schema mismatches, and validating completeness after migration.
How to Extract Metadata for Data Catalog Ingestion
Metadata extraction is the foundation of every useful data catalog. Without a reliable pipeline pulling technical, operational, and business metadata from your data sources, the catalog stays empty and nobody trusts it. This guide covers extraction patterns, pipeline architecture, and freshness strategies that work across catalog platforms, plus how AI-powered extraction handles document metadata that schema crawlers can't reach.
How to Extract Metadata from 3D Model Files
3D model files carry embedded metadata about authoring software, polygon counts, material references, animation rigs, units, and scene hierarchy. This guide covers what metadata each major format stores, how to extract it with desktop tools and code, and how to manage 3D file metadata across large projects.
How to Extract Metadata from CAD Files (DWG and DXF)
CAD file metadata includes drawing properties like author, title, revision history, creation and modification timestamps, units, coordinate systems, layer definitions, and block reference counts. This guide covers practical methods for extracting that metadata from DWG and DXF files using Python ezdxf, ODA File Converter, LibreDWG, and structured extraction platforms.
How to Extract Metadata from Database Exports (CSV, SQL, Parquet)
Database exports carry schema definitions, column types, row counts, encoding formats, and provenance information that most teams ignore during migration and cataloging work. This guide walks through extracting that metadata from CSV, SQL dump, and Parquet files using practical tools and code examples, then compares what each format actually gives you.
How to Extract Metadata from DICOM Medical Imaging Files
DICOM metadata extraction is the process of reading standardized tags from medical imaging files to retrieve patient demographics, imaging parameters, equipment settings, and study context. This guide covers the DICOM tag hierarchy, practical extraction with Python and pydicom, anonymization workflows for research datasets, and tools for managing medical imaging files at scale.
How to Extract Metadata from Docker Container Images
Docker container images carry structured metadata far beyond the filesystem layers themselves. OCI manifests, image configs, labels, layer history, and registry-level tags all hold information that matters for security audits, compliance checks, and build reproducibility. This guide covers five practical extraction methods, from docker inspect for local images to registry API calls for remote inspection without pulling.
How to Extract Metadata from Email EML and MSG Files
Email metadata extraction reads header fields, routing information, timestamps, sender and recipient data, and attachment references from EML and MSG email file formats. This guide covers the structural differences between these two formats, walks through programmatic extraction with Python and Node.js, and explains how to manage extracted metadata for forensic, compliance, and archival workflows.
How to Extract Metadata from Excel Spreadsheets
Excel spreadsheets store far more than visible cell data. Author names, revision history, external data connections, and hidden sheets all live inside the file as metadata. This guide covers how to extract that metadata using Excel's built-in inspector, Python's openpyxl library, and PowerShell, plus how to handle bulk extraction across hundreds of files.
How to Extract Metadata from Figma and Sketch Design Files
Design file metadata includes version history, component names, author information, frame dimensions, export settings, and style tokens embedded in Figma and Sketch files. This guide covers how to extract that metadata programmatically using the Figma REST API and Sketch's ZIP-based file format, with practical code examples for asset management and DAM integration.
How to Extract Metadata from Font Files (TTF, OTF, WOFF)
Font files carry a surprising amount of metadata in their OpenType name tables, from designer attribution and foundry info to license terms and embedding permissions. This guide walks through the practical tools and techniques for extracting that metadata from TTF, OTF, and WOFF files, whether you need to audit font licenses across a project, verify usage rights before distribution, or catalog design assets at scale.
How to Extract Metadata from Geospatial Files (GeoTIFF, Shapefile)
Geospatial metadata describes the spatial properties of geographic data files: coordinate reference systems, bounding boxes, pixel resolution, band counts, and attribute schemas. This guide covers practical methods for extracting that metadata from GeoTIFF, Shapefile, GeoJSON, and GeoPackage formats using command-line tools, Python libraries, and desktop GIS software.
How to Extract Metadata from Git Repositories
Git repositories hold far more than source code. Every commit stores author details, timestamps, diff stats, branch references, and GPG signatures that are valuable for analytics, compliance audits, and migration planning. This guide covers practical methods for pulling that data out and putting it to work.
How to Extract Metadata from JPG and JPEG Photos
JPEG photos embed metadata in APP marker segments that most image viewers never show you. This guide explains where EXIF, IPTC, and XMP data physically lives inside a JPEG file, then walks through five extraction methods from command-line tools to AI-powered batch processing.
How to Extract Metadata from Jupyter Notebooks (ipynb Files)
Jupyter notebooks store structured metadata at the file, cell, and output levels inside their JSON-based .ipynb format. This guide walks through extracting kernel specs, language info, execution timestamps, cell tags, and custom metadata fields using raw JSON parsing and the nbformat Python library.
How to Extract Metadata from Notion Pages and Databases
Notion databases hold structured metadata that many teams rely on for project tracking, content management, and CRM workflows. This guide covers how to extract that data programmatically through the Notion API, handle pagination for large datasets, normalize the nested property format into clean output, and store results in external systems.
How to Extract Metadata from Photoshop PSD Files
PSD files store far more metadata than JPEGs or PNGs. Beyond standard XMP and IPTC fields, they contain layer names, blend modes, color profiles, smart object references, and Photoshop-specific resource blocks. This guide covers how to extract all of it using ExifTool, Python, and automated extraction workflows.
How to Extract Metadata from PNG Files
PNG files store metadata in discrete chunks rather than the APP markers used by JPEG. This guide explains the five main PNG metadata chunk types, walks through extraction with ExifTool, Python, and online tools, and shows how to automate metadata extraction for large image collections.
How to Extract Metadata from PowerPoint Presentations
Guide to metadata extraction from powerpoint presentations: PowerPoint metadata encompasses document properties, slide notes, embedded media information, revision history, and hidden content stored within .pptx files. This guide walks through every layer of metadata in a presentation file and shows you how to extract, audit, and manage it using built-in tools, programmatic methods, and cloud-based platforms.
How to Extract Metadata from RAW Camera Files (CR2, NEF, ARW)
RAW camera files like Canon CR2, Nikon NEF, and Sony ARW store far richer metadata than JPEGs, including proprietary MakerNote tags, lens correction profiles, and full shooting parameters. This guide walks through extracting that metadata with command-line tools, Python libraries, and GUI applications, plus how to handle vendor-specific tags and batch processing across large photo libraries.
How to Extract Metadata from Scanned Documents Using OCR
OCR metadata extraction converts scanned document images into structured, searchable data. This guide walks through the complete pipeline, from digitization to indexed output, with tool recommendations for each stage and tips for improving accuracy on real-world documents.
How to Extract Metadata from SharePoint Documents
SharePoint document libraries hold structured metadata across custom columns, content types, and managed metadata term stores. This guide covers three extraction methods: the Microsoft Graph API for programmatic access, PnP PowerShell for bulk scripting, and Power Automate for low-code workflows.
How to Extract Metadata from TIFF Image Files
TIFF files carry more metadata than most image formats, from standard EXIF camera data to GeoTIFF spatial coordinates and multi-page document structures. This guide walks through extracting TIFF metadata with ExifTool, Python, and GDAL, then shows how to automate extraction at scale with AI-powered tools.
How to Extract Metadata from Web Pages (Open Graph, Schema.org, and Twitter Cards)
Web pages carry structured metadata in Open Graph tags, Schema.org JSON-LD, and Twitter Card elements. This guide walks through extracting all three protocols with Python and JavaScript, handling JavaScript-rendered pages, and building a pipeline that pulls consistent data from any URL.
How to Extract Metadata from WebP and AVIF Images
WebP and AVIF store EXIF, XMP, and ICC profile metadata inside container structures that older tools often skip entirely. This guide covers how to extract metadata from both formats using ExifTool, webpmux, Pillow, ExifReader, and libheif, with practical commands and code snippets for each approach.
How to Extract Metadata from YouTube Videos
YouTube video metadata includes title, description, tags, view counts, thumbnails, and dozens of other structured fields. This guide covers four practical ways to extract that data: the YouTube Data API v3, the yt-dlp command-line tool, custom Python scripts, and browser-based viewers.
How to Extract Metadata from ZIP and Archive Files
Archive metadata includes container-level properties like compression method, encryption flags, and internal timestamps, plus the embedded metadata of each file inside. This guide covers how to extract that metadata from ZIP, RAR, 7z, and tar archives using ExifTool, Python, and 7-Zip on the command line.
How to Extract Metadata in Real Time on File Upload
Real-time metadata extraction on file upload parses file properties the moment a file is received, making metadata available for search, validation, and routing before the user leaves the upload screen. This guide covers the architecture, implementation patterns, and tooling for building extraction into your upload flow, including partial parsing for large files and AI-powered structured extraction.
How to Fix the Google Drive Download Quota Exceeded Error
When multiple active AI agents and developers pull files from a single shared Google Drive link, they easily trigger the google drive download quota exceeded error. This lockout halts automated data pipelines and disrupts human-agent collaboration. This guide explains how to bypass this limitation using direct cloud import, granular workspace permissions, and collaborative spaces.
How to Generate Branded Share Links via Fastio API
File delivery is often the weakest link in automated workflows. Using the Fastio API, developers can automate the creation of custom-branded share links, allowing AI agents to easily deliver finalized assets to human clients. This guide covers how to implement programmatic branded shares, from initial setup to tracking access events via audit logs. It provides everything developers need to build intelligent, autonomous workspaces that prioritize professional presentation.
How to Handle Files in No-Code AI Agents
No-code AI agent builders let you create file-processing workflows without writing code. This guide shows how to add file storage, connect cloud services, and build agents that can read, process, and deliver files to users.
How to Handle Files in Pydantic AI Agents
Pydantic AI agents need valid file handling to go beyond text processing. Learn how to upload documents, store files, and process data using Pydantic's validation with the Fastio MCP server.
How to Implement Agent-to-Agent Communication Protocols Using Shared Files
File-based agent communication uses a shared workspace as a 'blackboard.' Agents post tasks, results, and state updates in a central spot where the whole team can see them. This approach lets multi-agent systems coordinate complex workflows without the constant chatter of traditional API calls. By using persistent files, teams create a permanent audit trail and can handle large datasets that would normally overwhelm network protocols.
How to Implement AI Agent File Deduplication Techniques
AI agent file deduplication removes duplicate files generated by autonomous agents in shared workspaces. Agent fleets naturally produce redundant outputs during retry loops, iterative refinement, and parallel executions, consuming storage and context windows rapidly. By implementing intelligent deduplication techniques like cryptographic hashing and content analysis, engineering teams can save up to 60% of their storage footprint.
How to Implement AI Agent RBAC File Permissions
RBAC for AI agent file permissions is a security model that assigns file access rights based on role, task scope, and trust level. Implementing these controls ensures that autonomous agents only read, write, or delete files they are authorized to handle, reducing unauthorized data access risks.
How to Implement API File Versioning: A Complete Developer Tutorial
File versioning with the Fastio API lets applications programmatically store, track, and roll back document iterations without duplicating filenames. This tutorial covers the exact REST API paths needed to manage file iterations securely in multi-agent environments. We will look at how to protect against agent hallucination overwrites by keeping historical backups.
How to Implement Fastio API Chunked Uploads and Streaming
Chunked uploads let developers transfer massive files to Fastio by breaking them into smaller, resumable parts. This Fastio API chunked uploads and streaming guide walks you through the steps to implement these transfers. You will learn how to handle network interruptions, improve your streaming logic, and maintain high success rates for your applications.
How to Implement Fastio API Large File Chunked Uploads
Chunked uploading in the Fastio API splits large files into manageable segments, ensuring reliable transmission over unstable networks without exhausting agent memory. This guide covers how to initialize, upload, and complete parallel chunked sessions for massive payloads.
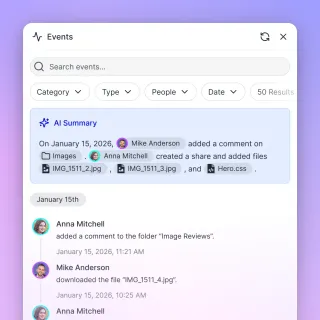
How to Implement Fastio API Real-Time File Event Notifications
File sharing is the practice of distributing digital files between users over a network, but when AI agents collaborate, they require instant context. Fastio API real-time file event notifications solve this by streaming updates via a WebSocket events feed and activity polling, ensuring agents always have the latest context. This guide covers how to monitor feeds, coordinate concurrent writes with advisory file locks, and reduce latency.
How to Implement File Locks with the Fastio API
Guide to implementing file locks with the Fastio API: learn how to acquire, heartbeat, and release advisory file locks to coordinate multi-agent writes safely.
How to Implement Generative UI File Uploads with Fastio API
Guide to implementing generative file uploads with fastio api: Generative UI file uploads use LLMs to dynamically render interactive upload components backed by the Fastio API based on user intent. This approach is rapidly replacing static forms in AI-native applications, allowing developers to handle binary files smoothly within conversational interfaces. This guide covers the complete implementation flow, from configuring the AI SDK to securely routing file streams directly to Fastio workspa
How to Implement Multi-Agent Context Sharing Patterns
Multi-agent context sharing patterns are architectural frameworks that define how AI agents exchange state and memory. Efficient sharing allows teams to coordinate multiple agents without redundant processing or context conflicts. Implementing the right pattern can help multi-agent systems complete complex tasks up to four times faster than isolated agents.
How to Implement Zero Trust File Access with Fastio API
Implement zero trust file access with Fastio API by validating tokens and applying RBAC to every file operation. No implicit permissions exist, so each request proves authorization. This prevents unauthorized access even after network perimeter breaches. Over 60% of data breaches start with compromised credentials, but zero trust cuts average breach costs by $1.76 million.
How to Import Cloud Files for AI Training Data
ML teams pull training data from an average of three or more sources, and data preparation consumes roughly 80% of project time according to CrowdFlower's data science report. Consolidating datasets from scattered cloud providers into a single workspace cuts that overhead significantly. This guide walks through five steps to import cloud files for AI training, from auditing your sources to validating the imported data.
How to Manage AI Agent Artifacts: Persistent Storage for Agent Outputs
AI agent artifacts are the tangible outputs created during agent tasks: code, documents, data visualizations, and structured data that need persistent storage and versioning. While Claude Artifacts popularized the concept, production agent systems require reliable storage that fits into team workflows. This guide covers artifact types, storage strategies, and how to move beyond chat UIs to artifact management where agents save work directly to shared workspaces.
How to Manage AI Agent Background Processing Files
Background processing enables AI agents to handle long-running tasks asynchronously, storing intermediate results and final outputs for later retrieval. By decoupling execution from ingestion, agents can process massive datasets without blocking. This guide explores architecture patterns for reliable async agent workflows.
How to Manage AI Agent File Versions
Version management lets AI agents track, compare, and restore files they create.
How to Manage AI Content Generation Agent Files
AI agents generate thousands of files: drafts, metadata, and images. Standard storage can't handle the volume. To keep publishing workflows moving, you need a structured system with versioning and API access.
How to Manage API Sharing Permissions and Link Expiration
The Fastio API lets developers generate secure, time-limited sharing links to enforce data governance during agent-to-human handoffs. Managing sharing permissions and link expiration helps secure modern applications, especially for agent-to-human workflows. Expiring links automatically reduce the risk of unauthorized data access.
How to Manage Custom File Metadata with Fastio API
Custom file metadata in Fastio allows developers to attach application-specific key-value pairs to files to improve search and organization. Using these programmatic file attributes, developers and automated workflows can retrieve context instantly without needing to parse entire file contents. This guide details exactly how to implement custom metadata schemas via the Fastio API to build scalable agentic workspaces.
How to Manage Fastio File Metadata with Drizzle ORM
Managing Fastio file metadata with Drizzle ORM lets developers store and query agent workspace data in Postgres with full type safety. This approach syncs file details like IDs, sizes, and AI states from the Fastio API to a local database. Caching metadata reduces repeated API calls and enables complex relational queries beyond API limits.
How to Manage Fastio File Metadata with Prisma ORM
Managing Fastio file metadata with Prisma ORM involves setting up a schema matching Fastio's file and workspace IDs. Poll the activity feed or consume WebSocket events to keep your database current. You can then query files with app data using Prisma's type-safe client. Prisma is trusted by more than 500k monthly active developers and works well for workspace-file relationships. Developers use it to track agent uploads, check usage, or build dashboards. Start with the Prisma schema, followed by the event handler.
How to Manage File Versioning for AI Agents
AI agents can generate huge volumes of files during iterative tasks, often overwriting previous best attempts. Effective file versioning creates an automatic safety net, allowing developers to compare iterations, roll back to stable states, and audit the full history of an agent's work.
How to Manage Files for Image Generation Agents
Image generation agents create thousands of files in minutes. Learn how to organize prompts, version outputs, and automate storage workflows to keep your creative library searchable and organized.
How to Manage Files for Resume Parsing Agents
Managing files for resume parsing agents means organizing candidate documents for AI recruitment systems. Learn to build secure workflows that extract structured data from different file types.
How to Manage Files in Rasa Chatbots
Rasa file management includes storing conversation data, training files, model artifacts, and user documents. Rasa handles training data well, but real-world assistants need a plan for runtime files. You need to handle user uploads, generate reports, and secure your model versions.
How to Manage Files with Google ADK Agents
Google ADK (Agent Development Kit) provides a structured way for agents to manage binary data through the Artifacts pattern. This guide explains how to implement persistent storage, session services, and tool integrations to build strong file handling into your AI agent workflows.
How to Manage Files with the Gemini API
Google's Gemini API offers powerful multimodal capabilities, allowing you to analyze images, audio, and video directly. However, its native file storage is transient, with a 48-hour expiration window.
How to Manage Files with the OpenAI Assistants API
Managing files in the OpenAI Assistants API requires more than just a simple upload. It involves structuring knowledge through vector stores, balancing file limits, and choosing between tools like file search and code interpreter. This guide covers how to upload, organize, and automate the lifecycle of files for assistants that need to process complex documents and large datasets efficiently.
How to Manage Google AI Studio Files
Google AI Studio lets developers upload documents, images, and video for Gemini's large context window. But the file expiration policy hurts production workflows.
How to Manage Google Shared Drive Permissions for AI Agent Rooms
Setting up AI agent rooms requires precise mapping of Google Shared Drive permissions to avoid data loss and rate limits. This guide explains how to scope service account access using Google's five standard roles, handle folders with limited access, construct API requests using correct query parameters, and coordinate files in Fast.io workspaces.
How to Manage IPTC Metadata as a Photographer
IPTC metadata is the international standard for describing and identifying photo content. This guide covers the full workflow from building reusable templates through batch editing at import, keywording for stock agencies, and delivering files with clean metadata intact. It also covers the 2025.1 standard update that added fields for AI-generated images.
How to Manage Logistics Files with AI Agents
AI agent logistics file management uses autonomous AI to handle supply chain documents like manifests, invoices, and tracking reports in real time. Agents organize files, update statuses, and share with teams, cutting manual work. Fastio provides intelligent workspaces where agents and humans collaborate using a consolidated MCP toolset and built-in RAG for semantic search once Intelligence is enabled.
How to Master WhatsApp AI Agent File Management
WhatsApp agents need more than text to be useful. Learn how to set up your bot to receive PDFs, images, and videos, and store them securely to bypass API limits.
How to Normalize Metadata Across File Formats
Different file formats store metadata in incompatible standards. EXIF handles photos, ID3 covers audio, Dublin Core describes documents, and IPTC and XMP bridge parts of the gap. Metadata normalization maps these fields into a single unified schema so you can search, compare, and manage files consistently regardless of format.
How to Optimize Google Drive Upload Speed for Agentic Workflows
Programmatic write requests frequently throttle Google Drive upload speeds due to API rate limits and quota unit exhaustion. Optimizing transfer rates requires adjustments to write concurrency, resumable chunk sizes, and client-side request pacing. Transitioning intermediate agent outputs to intelligent workspaces bypasses these API quotas while maintaining a versioned coordination layer for human-agent teams.
How to Preserve Metadata During File Conversion
Converting files between formats often strips embedded metadata without warning. Author names, creation dates, GPS coordinates, and copyright notices can vanish in a single Save As operation. This guide covers which metadata survives common conversions, which tools preserve it, and how to build a workflow that keeps your file properties intact.
How to Read Files in C++ within Secure Agent Sandboxes
C++ file reading in a secure agent sandbox requires strict path validation and memory boundaries. Standard path resolution fails to verify directory scope, leaving agents vulnerable to traversal attacks. This guide shows how to validate paths using canonical checks, read files line-by-line or into strings, and coordinate multi-agent file storage safely.
How to Read Files Line by Line in Python (and Avoid Agent Token Bloat)
Reading files line by line in Python prevents system memory exhaustion and AI agent token bloat. Using native iterators and custom generators allows software agents to process massive text logs incrementally. This guide explains how to implement memory-efficient readers and coordinate agent access within shared workspaces.
How to Remove EXIF Data Before Sharing Photos
Guide to exif data removal before sharing photos: Every photo you take with a smartphone embeds hidden metadata, including GPS coordinates, device details, and timestamps. This guide walks through how to remove EXIF data on every major platform, which sharing methods preserve it, and how to set up a reliable workflow for stripping metadata before files leave your control.
How to Resolve Paths Safely in C++ with std::filesystem::absolute
When building AI agent workspaces, resolving untrusted file paths is a critical security boundary. This guide explains why std::filesystem::absolute fails to prevent directory traversal and how to use std::filesystem::canonical to secure path resolution.
How to Run Metadata Extraction with Serverless Cloud Functions
Serverless functions let you extract metadata from files on demand without provisioning or managing servers. This guide covers packaging binary tools like ExifTool and FFprobe as AWS Lambda layers, wiring S3 event triggers for automatic processing, and building extraction pipelines that scale to thousands of concurrent files while charging only for compute time used.
How to Save Structured Output Files from AI Agents
AI agents that produce structured output files, not just chat messages, can hand off work to other systems, create audit trails, and avoid expensive re-processing.
How to Score and Validate Metadata Quality Before It Hits Production
Metadata quality scoring assigns numeric ratings to extracted metadata based on completeness, accuracy, consistency, and timeliness. This guide walks through building quality checks that catch gaps before metadata enters production systems, from required field validation to cross-field logic rules and AI confidence scoring.
How to Search and Query Files by Metadata Attributes
Metadata search lets you find files by their properties, such as author, creation date, dimensions, or custom tags, instead of relying on filenames or full-text content. This guide covers six practical methods: macOS Spotlight and mdfind, Windows Advanced Query Syntax, Linux find with exiftool, cloud storage APIs, dedicated DAM platforms, and AI-powered semantic search. Each approach suits different workflows, and you can combine them for precise, cross-platform file retrieval.
How to Secure C++ Agent Sandboxes With std::filesystem::permissions
Dynamic file creation by autonomous coding agents introduces the risk of file corruption and privilege escalation. Securing a C++ agent execution environment requires restricting local directory access at the operating system level. Using std::filesystem::permissions, developers can enforce read-only and owner-restricted access policies immediately after an agent generates a file. This tutorial walks through setting up permission boundaries and handing files off to shared workspaces.
How to Secure Fastio API Uploads with Clerk Authentication
Securing Fastio uploads with Clerk involves validating the Clerk JWT on your backend before generating a Fastio presigned upload URL. This prevents unauthorized users from consuming your storage and avoids unexpected billing. This guide shows you how to integrate Clerk authentication with Fastio's upload API using API keys, MCP tools, or direct REST calls.
How to Secure File Sharing for AI Agents
AI agents need secure file access just like human teammates do, but their autonomous nature creates unique risks. This guide walks through encryption, granular permissions, version history, and audit trails for multi-agent file sharing, with practical setup steps you can follow today.
How to Secure Files Accessed by AI Agents
AI agent file security includes the access controls, encryption, and audit mechanisms that protect sensitive documents accessed by autonomous agents. With 73% of security teams concerned about agent data access, proper implementation reduces breach risk by 89%.
How to Secure Tool Calling File Access for AI Agents
Secure tool calling allows AI agents to interact with files safely while keeping credentials hidden. Insecure tools often lead to agent failures through remote code execution or data leaks. This guide covers security best practices, risks, and MCP setups for your agents.
How to Set Up a Claygent File Upload Workflow
Poor data quality costs organizations an average of USD 12.9 million annually, making accurate research critical for outbound sales campaigns [Gartner Data Quality Research]. A Claygent file upload workflow attaches documents like PDFs or CSVs to a Claygent's prompt context to guide its autonomous web research. By configuring these prompt context documents in the Builder, GTM teams ground AI research in their brand voice and product guidelines.
How to Set Up AI Agent File Indexing (The Easy Way)
Most AI agent file indexing requires complex Python pipelines and vector databases. This guide shows you how to skip the infrastructure setup and give your agents instant, searchable access to documents using Fastio's built-in Intelligence Mode.
How to Set Up AI Agent File Sync Across Sessions
AI agent file sync maintains consistent file state across agent runs and workspaces. Without synchronization, agents lose intermediate files and progress whenever they restart between sessions. Fastio provides persistent cloud workspaces where agents can upload, update, and retrieve files using MCP tools or REST APIs. This architecture supports complex data processing pipelines, multi-step reasoning, and multi-agent collaboration.
How to Set Up AI Agent Shared KB
A shared KB lets multiple AI agents access the same indexed knowledge base in one workspace. It avoids duplicate data and helps agents work together on tasks like analysis or summarization. Turn on Intelligence Mode in Fastio for automatic file indexing and semantic search. Agents use a consolidated MCP toolset matching human capabilities, including advisory file locks for concurrent access. The 14-day Business Trial provides generous storage and credits.
How to Share a Google Drive Folder with AI Agents
Sharing Google Drive folders with AI agents requires balancing API limits, authorization protocols, and security risks. While service accounts and OAuth keys provide programmatic access, recursive scans often trigger Google Drive API throttling and expose sensitive data. This guide explains how to configure Node.js code for folder sharing, handle rate limits, and transition to structured workspaces that support multi-agent collaboration.
How to Share Files Between Multiple AI Agents
Multi-agent file access lets AI agents read, write, and share files through a centralized storage system with proper access controls.
How to Share Large Files on Google Drive with AI Agent Rooms
Sharing large files on Google Drive with AI agent rooms requires managing API quotas, authorization tokens, and versioning. While Google Drive supports files up to 5TB, recursive scans from automated agents frequently trigger rate limits and sync conflicts. Ingesting these files into a Fast.io workspace takes agent reads off the Drive API entirely and gives humans and agents one shared, version-controlled place to work.
How to Test Fastio API File Uploads with Vitest
Guide to testing fastio api file uploads with vitest: Testing Fastio file uploads with Vitest involves using vi.mock() to intercept the Fastio Node.js SDK and simulate successful or failed upload responses. This guide shows you how to set up reliable unit tests that cover happy paths, error handling, and edge cases without making actual network requests.
How to Track C++ File Modifications with std::filesystem::last_write_time
Tracking file modification times is essential for C++ applications synchronizing local files with shared workspaces. However, standard library functions like std::filesystem::last_write_time follow symbolic links by default, creating sandbox escape vulnerabilities. This guide explains how to get and set file times securely within restricted environments.
How to Unzip Files in Google Drive (And Streamline Agentic Access)
Unzipping files in Google Drive refers to extracting compressed folder contents, a task that currently requires third-party add-ons or downloading files locally. Identity-based attacks targeting Google Workspace rose by 127% year-over-year in 2025, showing the risks of third-party integrations. This guide covers how to unzip archives via local workflows, Workspace Marketplace apps, and secure workspaces designed for programmatic agent access.
How to Upload a Base64 String as a File to the Fastio API
Agents can upload a file as a Base64 string through the Fastio MCP upload tool. Pass content_base64 on a tools/call with action stream-upload, and the server decodes the string into a workspace file. This keeps the transfer inside JSON-RPC, which fits in-memory agent workflows and serverless functions. REST clients decode the Base64 locally and send the raw bytes as the multipart chunk field on POST /current/upload/. This guide covers encoding, the MCP request shape, size tradeoffs, and larger-file fallbacks.
How to Upload Files Directly from the Browser to Fastio
Open a Receive share, mint a guest token with POST /current/share/{share_id}/auth/guest/, then POST the file from the browser to https://api.fast.io/current/upload/ as multipart form data (name, size, chunk, action=create, instance_id, folder_id). Your application server stays off the byte path. Confirm the file with GET /current/events/search/ or GET /current/activity/poll/{entityId}, then let Ripley and MCP tools work from the same workspace.
How to Upload Files: Fastio API File Upload Tutorial
Following a Fastio API file upload tutorial is the fast way to get your applications talking to intelligent agent workspaces. The Fastio API lets developers upload files programmatically, connecting traditional software with AI workflows. This guide covers the upload process from basic authentication to handling complex transfers. You'll learn how to ensure your agents can consume API-uploaded files instantly.
How to Upload Large Files to Google Drive without Timeouts
Standard single-stream uploads to Google Drive often fail due to network timeouts and process crashes. Implementing the Resumable Upload API protocol or optimizing command-line tools like rclone allows automated agents to transfer massive files reliably. This guide explains how to configure chunked uploads and manage multi-agent file delivery within shared workspaces.
How to Use AI Assistants for File Management and Organization
AI assistant file management uses artificial intelligence to organize, categorize, search, and manage files automatically. These systems reduce the time workers spend daily searching for files through auto-tagging, smart search, and workflows that process documents without manual intervention. This guide covers five practical ways AI assistants can manage your files, the tools available, and how to get started with AI-powered organization.
How to Use Fastio API for Batch File Operations
The Fastio API batch file operations guide shows developers how to handle multiple file uploads, downloads, and management tasks at scale. Build on workspaces, shares, and chunked upload sessions to process batches efficiently in agent workflows. This tutorial covers authentication, key endpoints, error handling, and optimization tips grounded in official API docs.
How to Use LangChain Document Loaders
Document loaders are the first step in any RAG pipeline. They pull data from over 100 sources into a standard format that LLMs can work.
How to Use Multimodal AI Vision Models for Metadata Extraction
Vision-language models can look at an image or document and return structured metadata that traditional parsers miss entirely: scene descriptions, object labels, text transcription, and sentiment. This guide covers how multimodal extraction works, when it outperforms rule-based tools like ExifTool, and how to build a pipeline that combines both approaches for complete metadata coverage.
How to Use Redis as a Cache for AI Agent Files
Redis caching for AI agent files uses Redis as a high-speed intermediate cache layer for agent artifacts, processed documents, and frequently accessed data. This reduces latency from 50-200ms (object storage) to under 1ms and can cut storage API costs by 60-80%.
How to Use the LangChain File System for Persistent Data
The LangChain file system integration enables AI agents to read, write, and organize files on local disks or cloud storage. While most tutorials focus on loading data for analysis, this guide covers the essential "write" capabilities that allow agents to save their work, maintain persistent memory, and collaborate with human users.
Intelligent Document Processing APIs for Developers
Intelligent Document Processing (IDP) APIs use AI to automatically extract, classify, and validate data from unstructured documents like PDFs, images, and scanned files. Developers use IDP APIs to automate invoice processing, contract analysis, form extraction, and compliance workflows without building OCR and NLP pipelines from scratch.
LangChain Document Loader Alternatives for Better File Handling
LangChain document loader alternatives let you ingest files for RAG and agent applications without LangChain's complexity. This guide compares LlamaIndex, Unstructured.io, Docling, and specialized parsing tools so you can pick the right solution for your use case.
Metadata Extraction on Mobile: iOS and Android App Development Guide
Mobile metadata extraction works differently from desktop tools. iOS and Android each have their own APIs, permission models, and memory constraints that shape how your app reads EXIF, video, and document metadata. This guide walks through platform-native approaches with working code, covers the permission changes introduced in iOS 14 and Android's scoped storage, and shows how to handle extracted metadata at scale.
Metadata Extraction with Ruby Libraries: A Developer Guide
Ruby has a solid collection of gems for reading metadata from images, PDFs, audio files, and more. This guide compares the most useful options, from mini_exiftool's ExifTool wrapper to exifr's pure-Ruby EXIF parsing, pdf-reader for document properties, and taglib-ruby for audio ID3 tags. You will find installation steps, working code examples, and advice on building a multi-format extraction pipeline.
Modernizing File Server Resource Manager for Agentic Workflows
Modernizing File Server Resource Manager configurations for agentic workflows allows teams to transition from rigid directory limits to intelligent workspace storage. This comparative guide shows how replacing legacy active directory folder policies with cloud agent rooms enables multi-agent environments to query, index, and manage shared files safely.
Modernizing Windows File Server for AI Agent Workspaces
Bridging legacy Windows file server infrastructure to AI agent workspaces requires resolving key protocol and security mismatches. While legacy storage relies on SMB and Active Directory, AI agents need streamable HTTP and structured metadata. This guide explains how to establish secure gateways, run remote MCP servers, and use Fast.io as a neutral workspace substrate.
Multi-Agent File Sharing: Patterns, Storage & Code
How multiple AI agents share, read, write, and collaborate on files in production systems. Covers storage architectures, coordination patterns, and working code examples.
NAS File Server vs. Agent Rooms: Modernizing Team Storage
Comparing a traditional nas file server setup with cloud-based agent rooms highlights a core shift in team storage. Physical servers require complex firewall configurations for remote access, whereas modern workspaces provide persistent environments that auto-index files for AI grounding. This guide examines how teams can secure file access, coordinate multi-agent workflows, and transition from local hardware to intelligent workspaces.
OneDrive Shared Folders vs. Fast.io Agent Rooms: Solving the Storage Gap
When multiple AI agents and human teams collaborate in a shared folder, traditional sync tools like Microsoft OneDrive hit structural API limits. Fast.io Agent Rooms solve this gap by providing an API-first workspace with native Model Context Protocol support and automatic semantic indexing. This comparison reviews the file sharing constraints of Microsoft Graph and outlines the setup for agentic workspaces.
OpenAI Files API Alternatives for AI Document Storage
OpenAI Files API provides basic document storage for GPT applications, but has significant limitations for production AI systems. Alternative solutions offer persistent storage, support for files beyond 512MB, and compatibility with multiple AI frameworks beyond OpenAI.
Programmatic Google Drive Link Sharing vs. Decoupled Workspace API in Multi-Agent Workspaces
An AI agent tasked with delivering a client report on Google Drive must be granted permissions to modify the file's Access Control List. However, because the Google Drive API couples sharing permissions directly to the central storage environment, giving an agent the ability to write public permissions on a single file exposes the entire workspace to accidental disclosure or malicious data exfiltration.
Resolving Secure Sandbox Paths with std::filesystem::canonical
The std::filesystem::canonical function resolves all symbolic links, relative segments, and redundant separators in C++ filesystems. Naive path validation checks that do not resolve these components are vulnerable to path traversal attacks, especially in agentic environments where tools execute dynamically generated paths. This guide compares canonical, weakly_canonical, and absolute path operations and shows how to build a secure sandbox boundary in C++17.
Securing recursive_directory_iterator loops in agent sandboxes
Using std::filesystem::recursive_directory_iterator in C++ agent sandboxes can expose host systems to path traversal attacks if symbolic links and relative path segments are not validated. This how-to guide explains how to secure C++ filesystem iteration using canonical path validation and directory options.
Top 10 File APIs for AI Applications
A file API for AI applications provides programmatic endpoints for uploading, downloading, searching, and managing files that AI models and agents need to process, store, or deliver. This guide compares 10 leading file APIs built for AI workflows, from persistent storage to RAG-enabled document management.
Top 5 File Sharing Tools for AI Workflows
Over 60% of AI workflows involve document or file processing. Multi-agent systems can generate hundreds of artifacts per session. This guide evaluates the top five file sharing platforms designed to handle AI agent workflows, from API-first storage to LLM-native integrations.
Understanding Google Drive Shared Folder Limits in Multi-Agent Workflows
Google Workspace limits individual Shared Drives and My Drive folders to 500,000 items, a threshold that automated AI agents generating logs, code chunks, and assets can quickly exhaust. This guide analyzes these structural limits, details how they impact automated developer pipelines, and outlines strategies for coordinating multi-agent workflows.