Agent Observability and Evaluation
Knowing whether an agent is actually working. These pages cover tracing and structured logging, evaluation harnesses and benchmarks, hallucination detection, error handling and retries, performance and cost dashboards, and the testing practices that catch a regression before a customer does. Most of it comes down to keeping a durable record of what an agent did and what it produced, so the run can be replayed and the output compared.
Coverage runs from basic structured logging through to evaluation sets you can re-run against a change and compare. The pages are direct about what stays hard to measure, output quality above all, and they suggest proxies that are honest about their limits rather than dashboards that look precise while telling you nothing. Cost and latency tracking are treated as part of the same job.
21 guides in this topic.
Start here
Best AI Dashboard Builders for Agents: Top 8 Tools (2026)
AI dashboard builders provide visual interfaces and no-code tools to design, deploy, and customize user-facing dashboards for AI agent interactions. While agents often run headlessly, users need simple ways to monitor performance, review outputs, and intervene when necessary. This guide reviews the top tools for building these interfaces.
7 Best AI Agent Monitoring Tools for Production
AI agents introduce new failure modes that traditional APM tools can't catch, from infinite reasoning loops to excessive tool usage. This guide compares the top monitoring platforms for tracking agent behavior, cost, and output quality in production.
Best Tools for AI Agent Testing and Evaluation
Agent testing tools automate the evaluation of agent performance, checking for accuracy, loop detection, and goal completion. AI agents are probabilistic and dynamic, so standard unit tests often miss their complex behaviors. This guide reviews the top frameworks for evaluating LLM agents. It covers best tools for ai agent testing with practical examples.
How to Implement AI Agent Chaos Engineering
AI agent chaos engineering tests how multi-agent systems handle production stress. It involves injecting controlled failures to uncover weaknesses in agent interactions, shared state, and recovery mechanisms. This guide covers principles, step-by-step implementation, handling shared state during chaos, tools, and Fastio workspaces for real-world testing. Build reliable agentic workflows that withstand real-world disruptions.
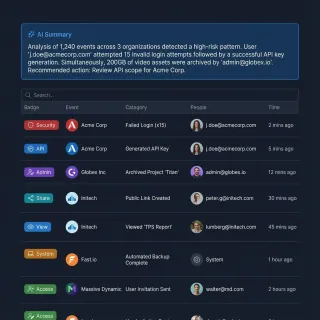
How to Use AI Agents with Jaeger Tracing
AI agent Jaeger tracing automates distributed trace analysis and alerting, providing deep visibility into complex agent workflows. By integrating OpenTelemetry with Jaeger, developers can visualize LLM chains, debug tool execution failures, and optimize performance. This guide covers the complete setup for instrumenting AI agents with Jaeger tracing, including Python and TypeScript examples, architectural best practices, and strategies for persistent log storage.
7 Best AI Agent Debugging Tools in 2026
AI agent debugging tools show you traces, states, and tool calls to make sure your agents work as intended. They help fix problems in single or multi-agent setups where errors usually come from tool calls or state mismatches. This comprehensive guide covers the top options, including a feature table, deep dives, and a look at why persistent file-based state is often the missing piece in debugging.
All guides
7 Best AI Agent Debugging Tools in 2026
AI agent debugging tools show you traces, states, and tool calls to make sure your agents work as intended. They help fix problems in single or multi-agent setups where errors usually come from tool calls or state mismatches. This comprehensive guide covers the top options, including a feature table, deep dives, and a look at why persistent file-based state is often the missing piece in debugging.
7 Best AI Agent Monitoring Tools for Production
AI agents introduce new failure modes that traditional APM tools can't catch, from infinite reasoning loops to excessive tool usage. This guide compares the top monitoring platforms for tracking agent behavior, cost, and output quality in production.
Best AI Dashboard Builders for Agents: Top 8 Tools (2026)
AI dashboard builders provide visual interfaces and no-code tools to design, deploy, and customize user-facing dashboards for AI agent interactions. While agents often run headlessly, users need simple ways to monitor performance, review outputs, and intervene when necessary. This guide reviews the top tools for building these interfaces.
Best Observability Tools for AI Agents: Monitor & Debug
AI agent observability tools provide visibility into agent reasoning, tool usage, and cost per run. Without them, developers face the "black box" problem, unable to explain why an agent loop failed or why costs spiked. This guide compares the top 7 tools for monitoring, tracing, and debugging autonomous agents in 2025.
Best Tools for AI Agent Evaluation (Evals)
Evaluating AI agents is no longer about simple "vibe checks." As agents move from prototypes to production, engineering teams need rigorous frameworks to measure accuracy, safety, and tool usage. This guide breaks down the best tools for AI agent evaluation in 2025.
Best Tools for AI Agent Testing and Evaluation
Agent testing tools automate the evaluation of agent performance, checking for accuracy, loop detection, and goal completion. AI agents are probabilistic and dynamic, so standard unit tests often miss their complex behaviors. This guide reviews the top frameworks for evaluating LLM agents. It covers best tools for ai agent testing with practical examples.
How to Build a Prompt Regression Testing Pipeline for AI Agents
A single token change in a system prompt can shift agent behavior as dramatically as a logic rewrite. Catching those shifts before production requires a regression testing pipeline with four pieces: a golden dataset of expected behaviors, behavioral assertions that test intent instead of exact output, CI gating that blocks bad merges, and delta tracking across prompt versions.
How to Build an AI Agent Performance Dashboard
Most teams running AI agents in production rely on raw logs to detect problems, which means failures go unnoticed for hours. An AI agent performance dashboard gives you a single screen showing task success rates, latency breakdowns, token costs, and error patterns in real time. This guide walks through the five metrics every dashboard needs, the tooling options for building one, and how to wire up file-operation tracking for agents that manage documents and deliverables.
How to Detect AI Agent Hallucinations in Production
AI agents hallucinate in 3% to 27% of outputs depending on the task and domain. This guide walks through a five-stage detection pipeline for catching ungrounded claims before they reach users, covering retrieval-augmented verification, semantic entropy, multi-agent validation, and persistent evidence storage for audit trails.
How to Evaluate AI Agents: A Comprehensive Framework
AI agent evaluation is the systematic process of measuring an autonomous agent's performance, reliability, and safety across tasks. Unlike static LLM testing, agent evaluation must account for multi-step reasoning, tool usage, and non-deterministic actions. This guide covers the essential metrics, frameworks, and benchmarks needed to build reliable AI systems.
How to Handle AI Agent Errors: Best Practices for 2025
Production AI agents frequently encounter errors during task executions. This guide covers essential error handling best practices, from exponential backoff to state checkpointing, that can reduce failure rates.
How to Implement AI Agent Chaos Engineering
AI agent chaos engineering tests how multi-agent systems handle production stress. It involves injecting controlled failures to uncover weaknesses in agent interactions, shared state, and recovery mechanisms. This guide covers principles, step-by-step implementation, handling shared state during chaos, tools, and Fastio workspaces for real-world testing. Build reliable agentic workflows that withstand real-world disruptions.
How to Implement Distributed Tracing for AI Agents
Distributed tracing for AI agents enables developers to track requests as they flow through complex multi-agent systems. By instrumenting agents with OpenTelemetry, you can visualize handoffs, debug non-deterministic behaviors, and optimize token usage across your entire fleet.
How to Manage SLOs for AI Agents
AI agent SLO management defines reliability targets for production agents, like 95% task success and under 5-minute latency. Without SLOs, multiple-multiple% of agents fail benchmarks due to untracked errors and state loss. Fastio workspaces provide audit logs, activity feeds, and Intelligence Mode for easy tracking and alerting. This guide explains key metrics, setup steps, Fastio integration, multi-agent coordination, and troubleshooting for reliable agentic workflows.
How to Master AI Agent Observability: Logs, Traces & Metrics
Autonomous agents are black boxes that can burn credits and fail silently. AI agent observability turns these opaque systems into transparent workflows. This guide covers the essential pillars of monitoring agents, from tracing multi-step tool calls to auditing file operations, so you can debug faster and optimize performance.
How to Mock Fastio API Endpoints for Unit Testing
Building reliable AI agent workflows means testing without active network connections. Mocking Fastio API endpoints lets you run unit tests without hitting the network or using up API credits. This guide shows how to set up mocks for Fastio services so your agents run predictably under any condition.
How to Test Fastio Event Bridges Locally with ngrok
Testing webhooks locally saves time when building file event integrations. This guide shows how to use ngrok to expose your local development environment and bridge Fastio event notifications. You will learn how to configure tunnels, validate webhook signatures, and troubleshoot common issues.
How to Test the Fastio API with Postman
Testing the Fastio API with Postman lets developers validate Bearer authentication, inspect /current/ route schemas with OPTIONS, and verify multipart uploads without writing application code. Proper API testing isolates integration issues in minutes rather than hours. This guide walks you through a Postman collection for Fastio storage, Ripley, and MCP tools.
How to Use AI Agents with Jaeger Tracing
AI agent Jaeger tracing automates distributed trace analysis and alerting, providing deep visibility into complex agent workflows. By integrating OpenTelemetry with Jaeger, developers can visualize LLM chains, debug tool execution failures, and optimize performance. This guide covers the complete setup for instrumenting AI agents with Jaeger tracing, including Python and TypeScript examples, architectural best practices, and strategies for persistent log storage.
Top LLM Observability Platforms 2026
Top LLM observability platforms for multiple track model performance, traces, and agent interactions in production. Teams building LLM apps deal with problems like hallucinations and latency. This list ranks the top tools, including pros, cons, and pricing for each. It covers tracing, evaluations, and multi-agent support gaps.
Top LLM Observability Platforms: LangSmith vs Arize vs HoneyHive
LLM observability platforms give you visibility into what happens between a user's prompt and your model's response. This guide compares seven leading platforms across pricing models (per trace vs per seat vs usage-based), tracing depth, evaluation frameworks, and production monitoring. Each entry includes real pricing, honest limitations, and guidance on which teams benefit most.