Connecting Grok to Cloud Storage and External Data via MCP
Grok Connectors link xAI models to cloud productivity tools and external files. While native connectors allow direct queries, indexing large document repositories through remote MCP servers avoids rate limits and token bloat. Here is how to configure Grok with cloud storage and structured data sources.

How Grok Connectors Access External Data
Pointing an AI assistant directly at a massive cloud drive leads to immediate rate limits and crawling delays because live file APIs were engineered for human folder browsing, not recursive context retrieval. When an agent attempts to inspect nested folders across an active company repository, sequential directory lookups quickly exhaust API quotas.
Grok Connectors are integrations within xAI's Grok assistant that allow the model to search, read, and retrieve data from third-party cloud productivity platforms and custom MCP endpoints. Connectors provide a standardized bridge between Grok's reasoning engine and the files, databases, and operational software that teams rely on every day.
Connectors are available to all Grok users and let Grok access your external tools and data sources directly within a conversation. They operate across Grok web, mobile applications on iOS and Android, and the developer API. Instead of forcing users to download files and attach them manually to chat prompts, connectors let Grok discover and inspect remote context during active conversations.
The Three Connector Categories in Grok
xAI organizes connectors into three distinct operational categories, each serving a different deployment model:
- Built-in Connectors. Maintained directly by xAI, these connectors provide native OAuth integration with core productivity suites. Available options include Google Drive, Gmail, Google Calendar, Microsoft OneDrive personal storage, Microsoft SharePoint, Outlook, and Salesforce. Once authorized, Grok interacts with these services on demand without requiring custom server maintenance.
- Connector Catalog. A directory of pre-configured third-party integrations that connect via OAuth. Notable services include Box, Notion, GitHub, Linear, Canva, and Vercel. These connectors allow Grok to read issues, pull requests, project boards, and stored media directly through vendor-maintained application endpoints.
- Custom MCP Connectors. For proprietary data stores, private infrastructure, and specialized storage platforms, Grok supports custom Model Context Protocol (MCP) servers. Teams configure a public HTTPS endpoint, and Grok dynamically negotiates tool definitions, resource schemas, and retrieval actions over the protocol.
In enterprise and team environments, connectors follow centralized administrative governance. An organization administrator provisions connectors through the xAI console before individual team members can authorize accounts and query company repositories.
How Function Calling Executes Remote Tool Requests
Under the hood, Grok uses structured function calling to interact with connected endpoints. When a user submits a prompt that references stored documents or external records, Grok evaluates the registered tool schemas provided by active connectors.
The model formats an internal JSON-RPC request containing targeted query parameters. The connector receives this call, authenticates with the target service, fetches matching records, and returns the response payload back to Grok's inference context.
Because this interaction happens dynamically during generation, the performance of the connection directly impacts chat responsiveness. Fast responses require lightweight data transfer, whereas unoptimized connectors that attempt to download whole directories introduce visible latency into the chat stream.
Related guides
- LangGraph S3 Connector: Connecting Graph Workflows to Cloud StorageA LangGraph S3 connector is an integration interface that enables LangGraph stateful agent workflows to read, persist,...
- ChatGPT Box Integration: Connecting Box Storage to AI AgentsA ChatGPT Box integration enables OpenAI models to query, summarize, and retrieve documents stored within Box cloud...
- How to Connect Dify AI Agents to Dropbox Cloud StorageA Dify Dropbox integration connects Dropbox cloud storage directories to Dify knowledge bases and agent workflows,...
- Gemini Google Drive Extension: Workspace Setup vs. Dedicated MCP StorageThe Gemini Google Drive extension is a built-in Google Workspace integration that allows Google Gemini to reference and...
- How to Connect Microsoft AutoGen Agents to S3 StorageAn AutoGen S3 connector is a registered tool or interface enabling Microsoft AutoGen conversational agents to read,...
- Can Gemini Access Google Drive? Extension Limits, Permissions, and MCP SearchGoogle Gemini connects to Google Drive through the Google Workspace extension (@Google Drive) for conversational...
More on this subject: Agent Integrations and APIs (195 guides)
Why Cloud Drives Encounter Rate Limits with Grok
Most teams already store their operating files in Dropbox, Google Drive, Box, or OneDrive. Connecting Grok directly to these native drives provides immediate access, but native cloud connectors exhibit sharp operational boundaries when scaled beyond a handful of individual documents. Traditional cloud storage APIs were created to synchronize files between personal computers and remote object stores, not to satisfy the high-frequency query bursts demanded by conversational language models.
Native connectors query external storage APIs in real time as Grok processes prompts. For a targeted search targeting a single spreadsheet or a short memo, this live lookup functions as expected. The challenge appears when an agent must answer questions that span hundreds of client files, project archives, or historical contracts. In these multi-document situations, direct API polling quickly degrades system performance.

API Throttling on Live Cloud Repositories
Cloud storage providers enforce strict rate limits on their developer APIs. Google Drive, Dropbox, Box, and Microsoft Graph each cap the number of requests an application can execute per minute.
When Grok attempts to locate a piece of information across an unindexed drive, the native connector must execute recursive directory traversals. Each folder listing, file metadata query, and document download consumes an API call against the tenant's rate limit. If Grok queries a deep folder structure, the connector can hit provider rate limits within seconds, causing timeouts or incomplete answers.
In addition, programmatic usage through the xAI API introduces another tier of constraints. Every xAI API team has per-model rate limits on two dimensions: requests per second and tokens per minute. When live connectors force the model to ingest large raw files to locate a single paragraph, token limits are consumed rapidly.
The Hidden Overhead of Context Stuffing
Direct document retrieval often results in context stuffing. When a native connector finds a candidate file, it frequently injects the complete text into the model's context window.
Extracting twenty pages of text to answer a single question about a contract clause consumes thousands of input tokens. This practice introduces three concrete problems:
- Inference Latency. Processing large context blocks increases time-to-first-token, making chat interactions feel sluggish.
- Cost Acceleration. Input tokens accumulate quickly across repeated multi-turn conversations, driving up API and subscription expenses.
- Needle-in-a-Haystack Degradation. Flooding the context window with extraneous text increases the risk that the model misses critical nuance buried deep in irrelevant paragraphs.
Relying on live folder browsing for broad document collections is inefficient. High-volume agentic workflows require a dedicated retrieval layer that indexes documents in advance and returns precise, relevant passages.
Bridging Existing Storage to Grok via Fast.io Workspaces
Rather than replacing existing cloud storage, organizations can place an intelligent workspace layer between their cloud drives and Grok. Fast.io serves as an intelligent workspace platform designed for agentic teams, allowing users to keep their existing files in Google Drive, Dropbox, Box, or OneDrive while providing Grok with an optimized, indexed MCP interface.
Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. It operates on predictable intervals rather than continuous, live, or real-time sync, ensuring files are consistently mirrored into an indexed environment without hammering third-party API rate limits.
SharePoint libraries are reached through the OneDrive connector, while Google Drive, Dropbox, Box, and OneDrive folders sync directly into Fast.io workspaces.
Scheduled Cloud Sync for Existing Drive Repositories
With Cloud Sync, teams maintain their existing storage habits. Team members continue working in their familiar Dropbox, Box, Google Drive, or OneDrive shared drives. Fast.io synchronizes the selected folders into an organization-owned workspace according to the configured schedule or upon manual trigger.
This architectural pattern decouples Grok's search requests from the third-party storage API. When Grok needs to inspect a project document, it queries Fast.io rather than making live API calls to Google Drive or Dropbox. This eliminates rate-limit friction on the primary cloud drive and isolates production file systems from automated query traffic.
The connector comparison is published at https://fast.io/benchmarks/ and that page is the only place its numbers live.
Semantic Search and Metadata Views
Once files arrive in a workspace, Fast.io's Intelligence Mode automatically indexes their contents for hybrid search, combining full-text keyword indexing with semantic search and metadata matching. Instead of loading an entire document into Grok's prompt, the agent searches the workspace and retrieves only the exact passages relevant to the user query.
For structured business data, Metadata Views transform unstructured documents into a live, queryable database. Users describe the fields they want extracted in natural language, and Fast.io builds a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date and Time types.
Metadata Views process PDFs, spreadsheets, Word documents, and scanned records without requiring manual OCR templates. Grok can query these extracted columns directly through MCP, retrieving contract expiration dates, invoice totals, or counterparty names without parsing the raw files.
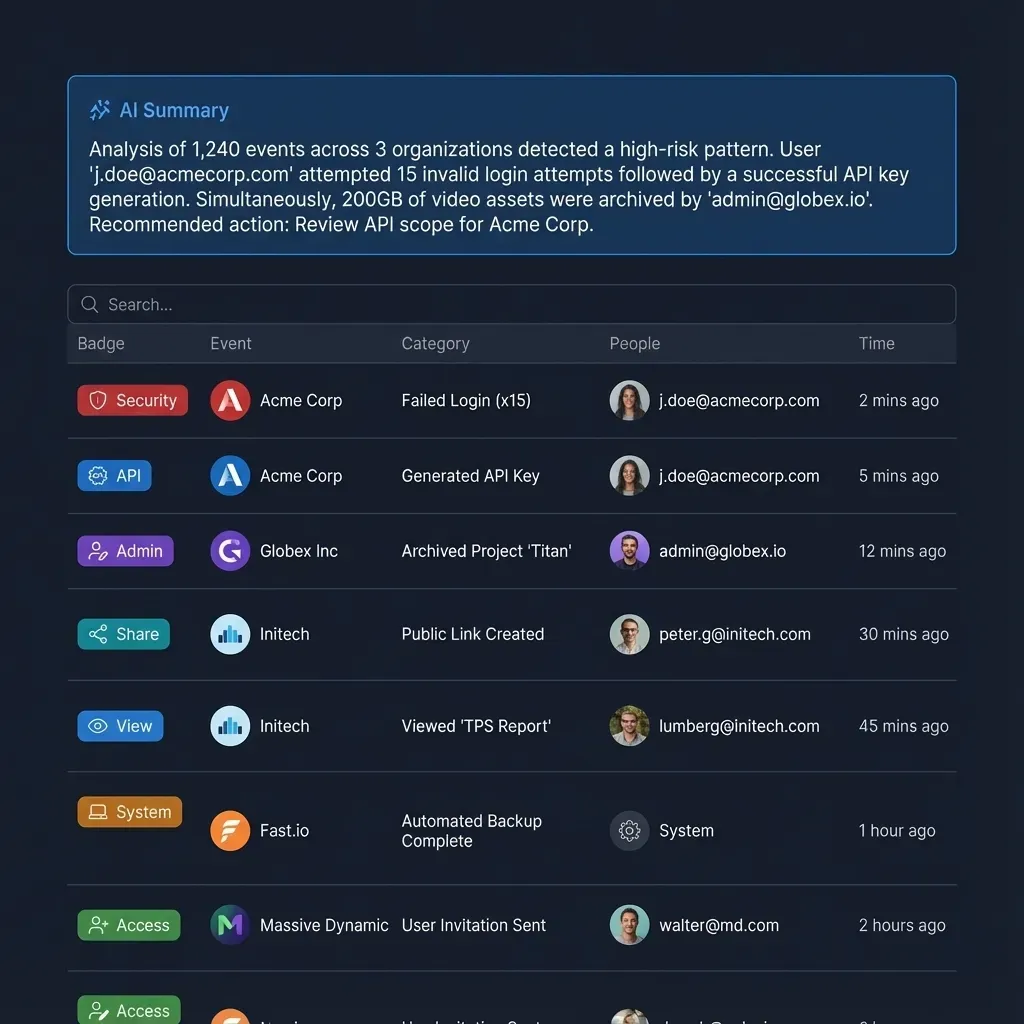
Workspaces also provide per-file version history and a detailed activity log. The activity log records changes across the organization, including file uploads, edits, moves, deletions, and permission adjustments, giving administrators clear visibility into agent modifications without logging read-only viewing events.
Connect Grok to Your Team Workspaces
Connect xAI Grok to persistent, indexed workspaces via Fast.io's remote MCP server. Search synced files, keep full version history, and start with a 14-day free trial on monthly plans.
How to Configure Grok with Fast.io via Model Context Protocol
Connecting Grok to Fast.io relies on the Model Context Protocol (MCP) using the Streamable HTTP transport. This open standard allows Grok to discover workspace capabilities dynamically and call storage operations securely over public HTTPS endpoints. By abstracting tool execution into standardized JSON-RPC schemas, MCP eliminates the need for proprietary SDKs or complex glue code.
Fast.io hosts a remote MCP server over Streamable HTTP. There are no local npm packages to install, and configuration requires only pointing Grok to the appropriate remote endpoint URL. The integration operates directly over the network, providing low-latency retrieval while enforcing organization access controls on every request.
Connecting Grok Web and Mobile Connectors
To link Grok's conversational interface to a Fast.io workspace, users configure a custom MCP connector:
- Navigate to grok.com/connectors in your browser.
- Click New Connector and select Custom.
- Enter
https://mcp.fast.io/mcp/toolsas the MCP server URL. - Complete the OAuth sign-in flow in the browser window that opens. Fast.io displays a permissions screen where you choose Read Only or Read and Write access and select the specific organizations and workspaces the connection can reach.
- Save the connector. Grok automatically discovers the exposed tools and makes them available in chat sessions.
Once provisioned, Grok can answer questions using workspace files across desktop and mobile chats. To revoke access at any time, remove the connector in Grok, open Fast.io Settings, navigate to Devices and Agents, select Connected Devices, and click Revoke.
Connecting Grok CLI and Coding Workflows
Developers building agentic pipelines with the Grok CLI or Grok Build coding agent connect through the dedicated coding endpoint at https://mcp.fast.io/mcp/code.
To register the server in the Grok CLI, run the standard MCP addition command:
grok mcp add --transport http fastio https://mcp.fast.io/mcp/code
When running headless scripts, automated jobs, or framework agents that cannot complete an interactive browser OAuth flow, authenticate by passing a scoped API key in the connection headers:
POST /mcp/code HTTP/1.1
Host: mcp.fast.io
Authorization: Bearer YOUR_FASTIO_API_KEY
Content-Type: application/json
Accept: application/json, text/event-stream
For detailed setup instructions, visit the official Fast.io MCP documentation.
The Consolidated Tool Surface and Advisory Locks
The Fast.io MCP server exposes a consolidated toolset divided cleanly between read operations and management actions. On the /mcp/tools endpoint, operations are organized into distinct tool pairs:
storagehandles reads via actions likesearch,list,details, andlock-status.storage_managehandles mutations via actions likemove,delete,lock-acquire, andlock-release.shareandshare_manageinspect and configure file sharing links.workspaceandworkspace_managemanage workspace boundaries and settings.
A sample tool invocation from Grok to search indexed documents follows standard JSON-RPC formatting:
{
  "jsonrpc": "2.0",
  "method": "tools/call",
  "params": {
    "name": "storage",
    "arguments": {
      "action": "search",
      "query": "Q3 financial summary",
      "workspace_id": "ws_8f91a2bc"
    }
  },
  "id": 1
}
When multiple agents or team members collaborate in the same workspace, Fast.io provides advisory per-file locks. An agent acquires a lease on a file using lock-acquire on storage_manage and releases it with lock-release. Advisory locks signal active editing to other participants without blocking concurrent writes; if two agents save changes simultaneously, per-file version history preserves both versions.
Multi-Agent Workflows and Team Collaboration Patterns
Integrating Grok with Fast.io creates a collaborative workspace where artificial intelligence agents and human colleagues share a single operational environment. Files, notes, and search indices remain accessible to both human members using the web interface and automated agents calling MCP tools.
This shared substrate prevents data fragmentation. Research outputs, generated charts, and summarized briefs land directly in the workspace rather than getting trapped in ephemeral chat threads. Because workspaces maintain centralized organization ownership, team leads retain complete visibility into what assets are created, modified, or shared across multi-agent workflows. Workspaces serve as a durable record of agent work across multiple projects and sessions.
Collaborative Notes and Agent Handshake
Fast.io includes Collaborative Notes kept beside files in the workspace. Notes allow agents and team members to record context, instructions, and run summaries without altering source documents.
Notes rely on version-checked saves rather than real-time co-editing. An agent running a document analysis pipeline can read a raw PDF, extract key metrics, and write a structured summary directly into a workspace note. A human teammate reviewing the project can read the note, verify citations, and append follow-up guidance for the next agent run.
Because Fast.io supports any LLM client, other tools like Claude Code, Codex, or Cursor can interact with the same workspace alongside Grok. One model can handle data extraction while another writes code against the output, with every file state captured in version history.
Ownership Transfer and Client Delivery Shares
Agentic systems frequently produce artifacts intended for clients or external partners. Fast.io supports ownership transfer, allowing an agent or consultant to provision an organization, configure workspaces, sync repositories, and transfer ownership to a human stakeholder while retaining administrative access.
When sharing files with external parties, teams create branded shares using Send, Receive, or Exchange modes. Branded shares can be durable or expiring, and administrators can disable file downloads to keep viewing restricted to the browser. External recipients do not consume organization seats and can access shared assets without registering for an account.
Plan Structure and Trial Provisioning
Fast.io operates on a subscription model structured around organization workspaces and AI compute credits. Every organization runs on a paid subscription, and monthly plans start with a 14-day free trial that requires a credit card.
Plan tiers accommodate varying team and storage requirements:
Sources
References used to verify factual claims in this guide.
-
Every xAI API team has per-model rate limits on two dimensions: requests per second and tokens per minute.
-
Connectors are available to all Grok users and let Grok access your external tools and data sources directly within a conversation.
Frequently Asked Questions
What are Grok Connectors?
Grok Connectors are integrations within xAI's Grok assistant that allow the model to search, read, and retrieve data from third-party cloud productivity platforms and custom MCP endpoints. They enable Grok to query external data sources directly inside conversations.
Can Grok access my Google Drive files?
Yes. Grok offers a built-in Google Drive connector that authenticates via OAuth. Alternatively, users can sync Google Drive folders into a Fast.io workspace using Cloud Sync, allowing Grok to query files via semantic search through an MCP connection.
How do I connect external data sources to Grok?
Users can add external data sources by visiting grok.com/connectors, clicking New Connector, and selecting either a pre-configured service or Custom. Custom connections use a public HTTPS URL pointing to a Model Context Protocol (MCP) server.
Does Grok support MCP servers?
Yes. Grok supports remote MCP servers over Streamable HTTP across its web interface, mobile applications, API endpoints, and the Grok CLI. Users configure custom MCP endpoints in connector settings or via developer configuration.
How do Grok Connectors differ between built-in and custom options?
Built-in connectors are maintained natively by xAI and authenticate directly via OAuth with supported SaaS services like Google Workspace and Microsoft 365. Custom MCP connectors allow teams to connect any external database, API, or indexed cloud workspace that implements the Model Context Protocol.
Does Fast.io sync with Google Drive, Dropbox, Box, and OneDrive?
Yes. Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. It operates on scheduled intervals rather than real-time synchronization, keeping external storage mirrored into an indexed workspace.
How does semantic search reduce Grok token consumption?
Rather than pulling entire multi-page documents over a live file connector, semantic search scans indexed text chunks and returns only the most relevant excerpts. This minimizes prompt token usage, lowers per-query latency, and prevents rate-limit exhaustion.
Related Resources
Connect Grok to Your Team Workspaces
Connect xAI Grok to persistent, indexed workspaces via Fast.io's remote MCP server. Search synced files, keep full version history, and start with a 14-day free trial on monthly plans.