Top LLM Agent Hosting Platforms Reviewed
Discover the top LLM agent hosting platforms that handle inference, tools, and state for production language model agents. LLM agents need 10x more compute than chatbots due to iterative tool calls, planning, and tool usage. This review covers 8 options with perf metrics, pricing, and features like persistent workspaces and MCP support.

How We Evaluated These Platforms
We tested platforms for agent essentials like cold starts under 2 seconds, pricing below $1 per million output tokens on 70B models, persistent storage, MCP tools, autoscaling, and easy deployment. We checked production readiness for each, drawing from official pricing pages and docs.
Related guides
- Best AI Agent Hosting Platforms in 2026AI agent hosting platforms provide compute, storage, and orchestration for deploying autonomous agents in production....
- Best Self-Hosted AI Agent Platforms (2025 Guide)Self-hosted AI agent platforms let teams run agents on their own infrastructure — keeping data on-premise and avoiding...
- Top 10 AI Agent Infrastructure Platforms in 2026AI agent infrastructure platforms build backends for multi-agent systems. The market is expected to grow from $7.63...
- Best Edge AI Platforms in 2026: Hardware, Software, and Fleet Management ComparedThe edge AI market reached $24.91 billion in 2025, yet most comparisons still separate hardware from software, leaving...
- Top AI Agent Hosting Providers in 2026AI agent hosting providers offer scalable runtime with persistent storage and tools for reliable operation. This list...
- 7 Best Agentic GitOps Platforms for 2026Agentic GitOps platforms use Git to manage AI agents. Agents handle infrastructure deployments independently, using Git...
More on this subject: Agent Infrastructure and Deployment (51 guides)
What Key Features Should You Prioritize in LLM Agent Hosting?
Effective LLM agent hosting balances several key factors:
Persistent State: Agents require durable storage for memory and artifacts across sessions, unlike ephemeral chatbot inference.
Tool Integration: Support for MCP or rich APIs for file ops, webhooks, locks.
Low Cold Starts: Under 2 seconds for responsive multi-turn interactions.
Scalable Pricing: Per-second GPU or per-token billing without idle costs.
Collaboration: Human-agent handoff, sharing, comments.
Platforms like Fastio fill gaps in persistence and MCP, while others excel in raw compute.
Define clear tool contracts and fallback behavior so agents fail safely when dependencies are unavailable. This improves reliability in production workflows.
Comparison Table
Give Your AI Agents Persistent Storage
Fastio gives teams shared workspaces, MCP tools, and searchable file context to run top llm agent hosting platforms workflows with reliable agent and human handoffs.
How to Choose the Right LLM Agent Hosting Platform?
Match your needs:
Stateful/multi-agent: Fastio (workspaces, MCP, locks, version history).
Fastio addresses persistence gaps in competitor offerings, with human handoff via ownership transfer.

Selection Checklist
Test integration with your LLM stack. For production agent teams, prioritize MCP support and persistent storage to address common gaps in competitor offerings. Try the Fastio Business Trial.
1. Fastio
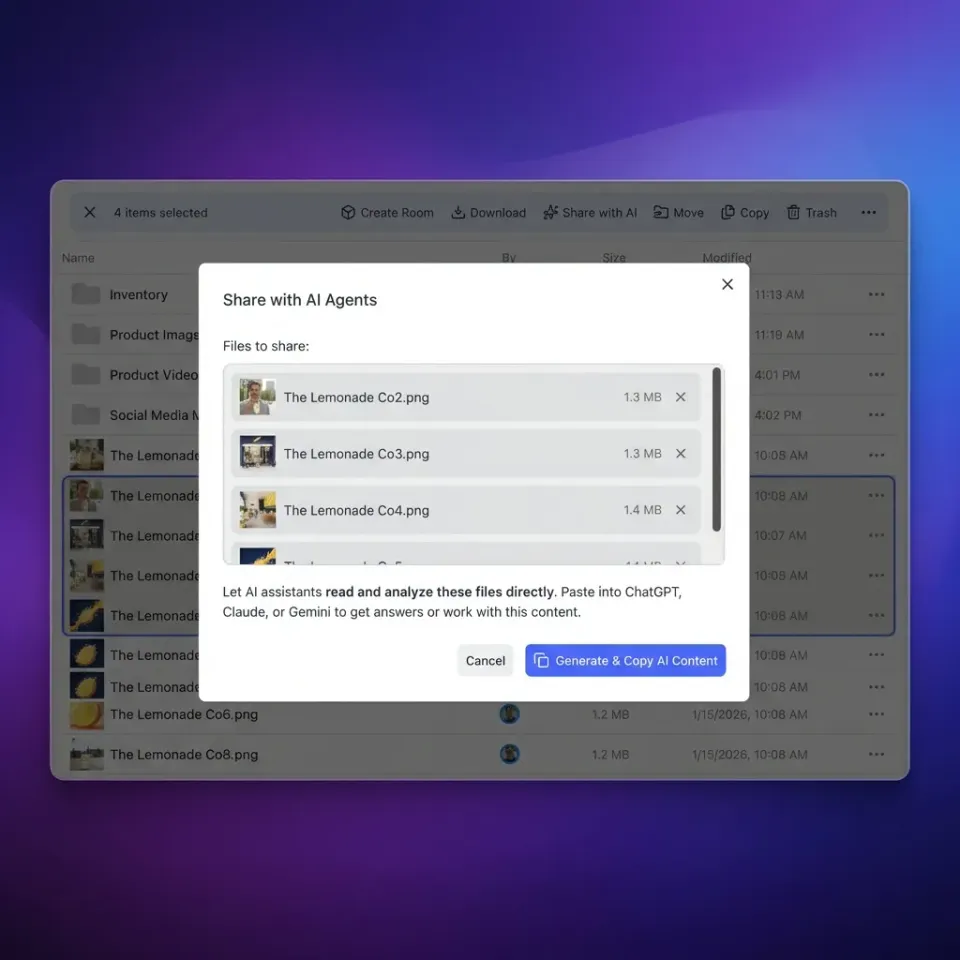
Fastio offers intelligent workspaces for LLM agents, including a consolidated MCP toolset via Streamable HTTP/SSE, built-in RAG, and persistent file storage. See the agent guide for full details.
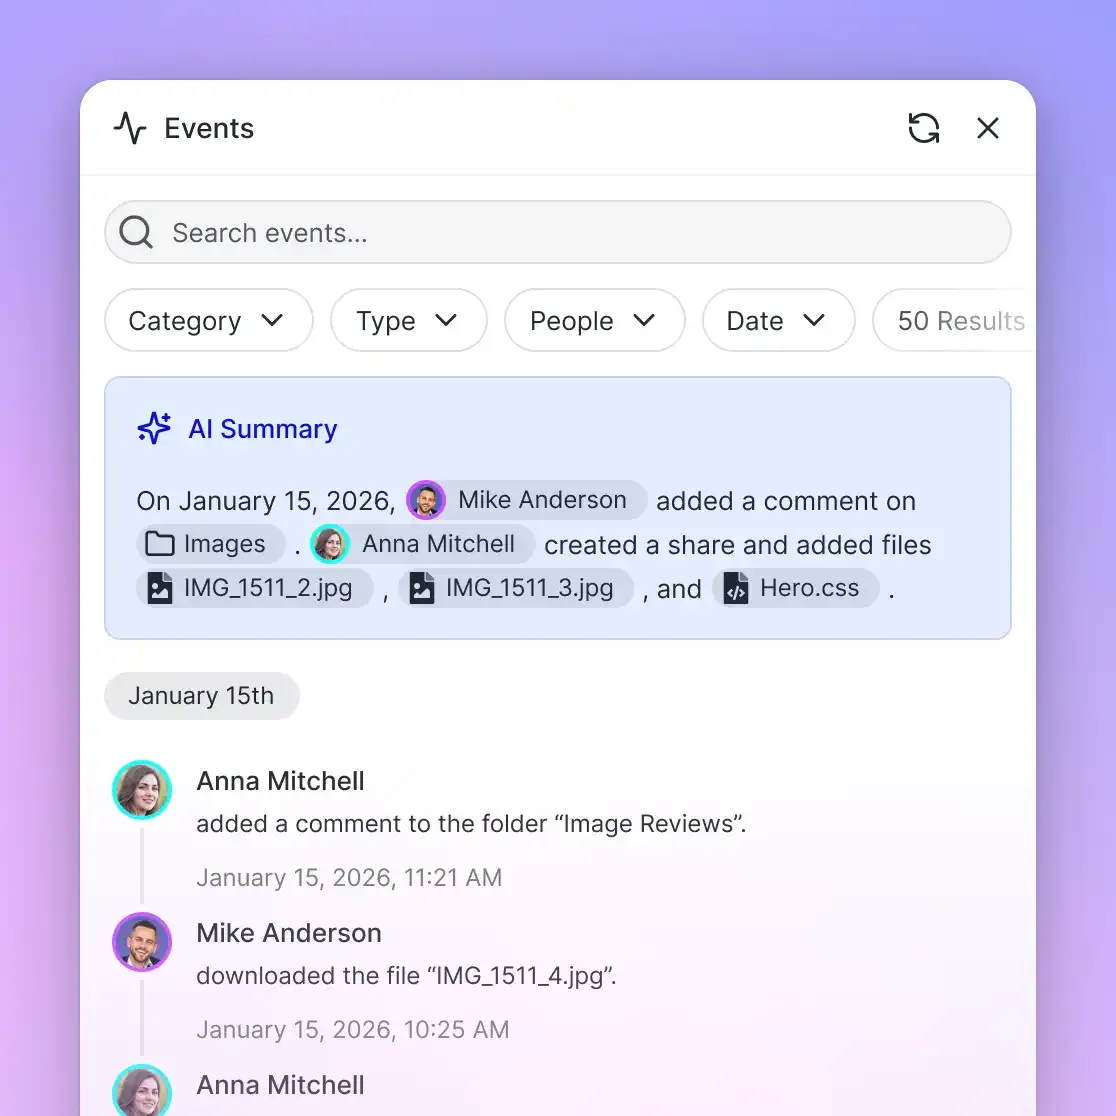
Unlike inference-focused platforms, Fastio provides the coordination layer: agents build workspaces, coordinate writes with advisory file locks, upload outputs, query with AI, collaborate via comments, and hand off to humans via ownership transfer.
Strengths
- 14-day Business Trial with usage-based credits.
- Version history for change tracking, real-time activity feed, and ownership transfer for production handoff.
- Universal LLM support via remote MCP connection at https://mcp.fast.io/mcp.
- Intelligence Mode auto-indexes files for semantic search and cited RAG queries.
Limitations
- Optimized for storage/tools, not GPU inference (pair with Replicate/Modal).
- Compute handled by external LLMs.
Best for: Stateful workflows, multi-agent teams, human collaboration.
Pricing: 14-day Business Trial; Starter from $29/mo. Source: Fastio Pricing.
2. Replicate
Replicate runs open ML models serverless via HTTP API.
Strengths
- Pay-per-second on GPUs like A100 ($5.04/hr).
- Auto-scales; vast model library.
- Quick prototyping.
Limitations
- No persistence; ephemeral.
- Basic tools.
Best for: Stateless agent inference.
Pricing: $0.000225-0.0028/sec GPU.
3. Modal
Modal offers serverless Python GPU functions.
Strengths
- Sub-second cold starts.
- Volumes for temp state.
- H100 $0.001097/sec.
Limitations
- Ephemeral; Python-only.
- No MCP.
Best for: Python agent jobs.
Pricing: $0.000164-0.001736/sec GPU.
4. RunPod
RunPod deploys GPU pods/serverless.
Strengths
- H100 $0.0014/sec; pre-warmed.
- Disk storage.
- Global regions.
Limitations
- Setup overhead.
- No native tools.
Best for: Custom GPU agents.
Pricing: $0.000164+/sec.
5. Fal.ai
Fal.ai specializes in serverless gen AI.
Strengths
- H100 $1.89/hr.
- Fast image/video for agents.
- Edge scale.
Limitations
- Gen-focused.
- No state.
Best for: Multimodal agents.
Pricing: $0.0005+/sec.
6. Baseten
Baseten deploys ML models with Truss.
Strengths
- Fast cold starts 100ms.
- Auto-scale.
- A100 $0.066/min.
Limitations
- Ephemeral.
- Model-centric.
Best for: Serving scale.
Pricing: $0.00058+/min CPU/GPU.
7. Together.ai
Together hosts open models.
Strengths
- Llama 70B $0.88/M.
- Distributed inf.
- Fine-tune.
Limitations
- No persistence.
- Model focus.
Best for: Open inf.
Pricing: $0.06-3.50/M tok.
8. Fireworks.ai
Fireworks delivers fast LLM inf.
Strengths
- <100ms cold; 10x vLLM.
- Function calling.
- 70B $0.90/M.
Limitations
- Inf only.
- No state.
Best for: Speedy chains.
Pricing: $0.10-0.90/M tok.
Which Platform Fits Your Agents?
For compute-heavy stateless: Replicate/Modal/Fireworks. For persistence/tools: Fastio. Multimodal: Fal.ai. Test trial options and platform tiers first.
Define clear tool contracts and fallback behavior so agents fail safely when dependencies are unavailable. This improves reliability in production workflows.
Sources
References used to verify factual claims in this guide.
-
LLM agents require 10x more compute than simple chatbots due to iterative tool calls and planning. LLM agents often require 5-10x more compute than simple chatbots due to planning, tool use, and reflection loops.
-
Fastio Business Trial: 14-day trial with usage-based credits requiring a credit card. Fastio 14-day Business Trial. Fastio pricing includes a 14-day Business Trial, with paid plans starting at $29 per month. Fastio provides a 14-day Business Trial while other providers commonly use credit-based trial tiers like Replicate.
-
Fastio offers a consolidated toolset.
-
Replicate $10 credit 1-5s cold start A100 (80GB) GPU at $5.04/hr. 70B model pricing targets under $1/M output tokens. Replicate T4 GPU $0.81/hr. Replicate pricing includes pay-per-second GPUs with A100 options around $5 per hour.
-
Modal H100 GPU $0.001097/sec (~$3.95/hr). Modal offers $30/month free credits. Cold start benchmarks under 2 seconds for production agents.
-
RunPod Credits <200ms cold start H100 ~$0.0014/sec. RunPod supports pre-warmed GPU options with pricing around 0.0014 per second.
-
Fal.ai Trial <2s H100 $0.0005/sec ($1.89/hr).
-
Baseten Credits 100-500ms cold start A100 $0.066/min (~$4/hr).
-
Together.ai Trial <1s Llama 70B $0.88/M tokens.
-
Fireworks.ai >16B models $0.90/1M output tokens. Fireworks.ai sub-100ms cold starts. Fireworks offers a free credit tier with pricing near $0.90 per million output tokens. Fireworks low-latency chains pricing around $0.90 and no built-in persistence. Fireworks can deliver sub-100ms cold starts and promotes large speedups over baseline vLLM.
-
This review covers 8 options with perf metrics, pricing, and features like persistent workspaces and MCP support.
-
Fastio offers intelligent workspaces for LLM agents, including a consolidated toolset via Streamable HTTP and SSE, built-in RAG, and persistent file storage. Fastio offers a consolidated MCP toolset over HTTP and SSE transports.
Frequently Asked Questions
What are the top LLM agent hosting platforms?
Fastio, Replicate, Modal, RunPod, Fal.ai, Baseten, Together.ai, Fireworks.ai stand out for inference, state, and tools.
Best platform for production LLM agents?
Fastio for persistent workspaces/MCP; Replicate/Modal for scalable inference. Match to needs like state vs speed.
Do LLM agents need more compute than chatbots?
Yes, 5-10x more due to planning, tools, reflection.
What is MCP in agent hosting?
Model Context Protocol for tools/state; Fastio offers a consolidated toolset via HTTP/SSE.
What trial options exist for agent hosting?
Fastio provides a 14-day Business Trial; others offer credits like Replicate $10.
Related Resources
Give Your AI Agents Persistent Storage
Fastio gives teams shared workspaces, MCP tools, and searchable file context to run top llm agent hosting platforms workflows with reliable agent and human handoffs.